CorpusMind Voice: From Speech to Searchable Corpus, Entirely on Your Machine
كوربَس مايند فويس: من الكلام إلى مجموعة لغوية قابلة للبحث، بالكامل على جهازك
Dr. Waleed Mandour (Sultan Qaboos University) · Prof. Wesam Ibrahim (Princess Nourah Bint Abdulrahman University) د. وليد مندور (جامعة السلطان قابوس) · أ.د. وسام إبراهيم (جامعة الأميرة نورة بنت عبدالرحمن)
CorpusMind Voice is the speech companion to the CorpusMind research environment. It ingests MP3, MP4, M4A, AAC, OGG, OPUS and WAV recordings, or captures live microphone input on desktop and mobile, and runs a six-stage, fully local pipeline: audio ingestion, word-level speech recognition with faster-whisper (tiny → large-v3, INT8, downloadable in-app), word- and phoneme-level forced alignment with Montreal Forced Aligner, prosodic analysis of fundamental frequency, intensity, jitter, shimmer and harmonics-to-noise ratio with Praat via Parselmouth, and bilingual disfluency detection. A built-in Linguistic Analysis suite computes frequency lists with DP dispersion, KWIC concordances with normalized, whole-word and regex matching, keyword detection with log-likelihood G² and the %DIFF effect size, collocations with MI, t-score and logDice, n-grams, Zipf rank-frequency curves, lexical diversity (MATTR/MTLD), readability and disfluency/prosody rates, all exportable to CSV. A cross-session Corpus tab aggregates every processed session with corpus-wide dispersion and concordance. The corpus itself saves to SQLite, JSON, CSV, TEI P5, Praat TextGrid, ELAN EAF, SRT and WebVTT. No audio, transcript, or metadata ever leaves the researcher's device: there are no cloud APIs, no telemetry, and no subscription. The result loads directly into CorpusMind with one click, closing the loop from spoken data to publication-ready corpus analysis.
كوربَس مايند فويس هو الرفيق الصوتي لبيئة كوربَس مايند البحثية. يستقبل ملفات MP3 وMP4 وM4A وAAC وOGG وOPUS وWAV، أو يلتقط مدخل الميكروفون مباشرة على سطح المكتب والمحمول، ويشغّل خط معالجة محليًا كاملًا من ست مراحل: استيعاب الصوت، والتعرف على الكلام بطوابع زمنية لكلمة بكلمة عبر faster-whisper large-v3 (بترميز INT8)، والمحاذاة القسرية على مستوى الكلمة والصوتونة عبر Montreal Forced Aligner، والتحليل التنغيمي للتردد الأساسي والشدة والتذبذب والرقّة ونسبة التوافقيات إلى الضجيج عبر Praat وParselmouth، وكشف عيوب الطلاقة باللغتين. ثم تحسب حقيبة التحليل اللغوي المدمجة قوائم التكرار مع توزّع DP، والكونكوردانس KWIC بأنماط المطابقة الطبيعية والكلمة الكاملة والتعبيرات النمطية، والكلمات المفاتيح مع اللوغاريتم الاحتمالي G² ومقياس %DIFF، والتجمّعات بمعاملات MI وt-score وlogDice، والمتتاليات، ومنحنى Zipf للرتبة والتكرار، والثراء اللغوي (MATTR/MTLD)، وسهولة القراءة، ومعدلات عيوب الطلاقة والتنغيم، وكلها قابلة للتصدير إلى CSV، فيما يجمّع تبويب المجموعة كل الجلسات المعالَجة في عرض واحد. وتُحفَظ المجموعة بصيغ SQLite وJSON وCSV وTEI P5 وPraat TextGrid وELAN EAF وSRT وWebVTT. لا يغادر أي صوت أو نص أو بيانات وصفية جهاز الباحث إطلاقًا: لا واجهات سحابية، ولا قياسات استخدام، ولا رسوم اشتراك. وتُحمَّل النتيجة مباشرة في كوربَس مايند بنقرة واحدة، فيكتمل المسار من البيانات المنطوقة إلى التحليل اللغوي الجاهز للنشر.
Privacy by Design: Your Recordings Never Leave Your Device
الخصوصية بالتصميم: تسجيلاتك لا تغادر جهازك أبدًا
CorpusMind Voice performs speech recognition, forced alignment, prosodic analysis and export as local processes on your own hardware. Zero network calls are made to third parties; the service worker caches only the application shell and never caches API responses; the optional assistant talks exclusively to a local LLM server (Ollama on 127.0.0.1:11434 or LM Studio on 127.0.0.1:1234, detected automatically) and clearly reports when neither is running. Interview data involving human subjects therefore remains under the researcher's sole custody, an essential guarantee for ethics-board protocols.
ينفّذ كوربَس مايند فويس التعرف على الكلام والمحاذاة القسرية والتحليل التنغيمي والتصدير كعمليات محلية على عتادك الخاص. لا تُجرى أي نداءات شبكية لأطراف خارجية؛ ويخزّن عامل الخدمة هيكل التطبيق فقط دون الاستجابات؛ ويتحدث المساعد الاختياري حصرًا مع خادم نماذج لغوية محلي (Ollama على العنوان 127.0.0.1:11434 أو LM Studio على 127.0.0.1:1234) يُكتشف تلقائيًا وينبّه بوضوح عند تعطّله. وبذلك تبقى بيانات المقابلات المتعلقة بالمشاركين البشريين تحت حيازة الباحث وحده، وهي ضمانة جوهرية لبروتوكولات لجان الأخلاقيات.
Why CorpusMind Voice?
لماذا كوربَس مايند فويس؟
Everything a spoken-corpus researcher needs between the recorder and the analysis environment, in one free, open-source, offline application. كل ما يحتاجه باحث المجموعات المنطوقة بين مسجّل الصوت وبيئة التحليل، في تطبيق واحد مجاني ومفتوح المصدر يعمل دون اتصال.
Files or Live Microphone
ملفات جاهزة أو ميكروفون مباشر
Ingest MP3, MP4, M4A, AAC, OGG, OPUS, FLAC and more, or capture speech directly from the microphone, on Windows, macOS and Linux as well as in the mobile PWA; recording works in the lab, in the field, or in the interview room.
استقبل تسجيلات MP3 وMP4 وM4A وAAC وOGG وOPUS وFLAC وغيرها، أو التقط الكلام مباشرة من الميكروفون على ويندوز وماك ولينكس وفي تطبيق المحمول؛ يعمل التسجيل في المختبر أو الميدان أو غرفة المقابلة.
Word-Level Timestamps & Confidence
طوابع زمنية ودرجات ثقة للكلمة الواحدة
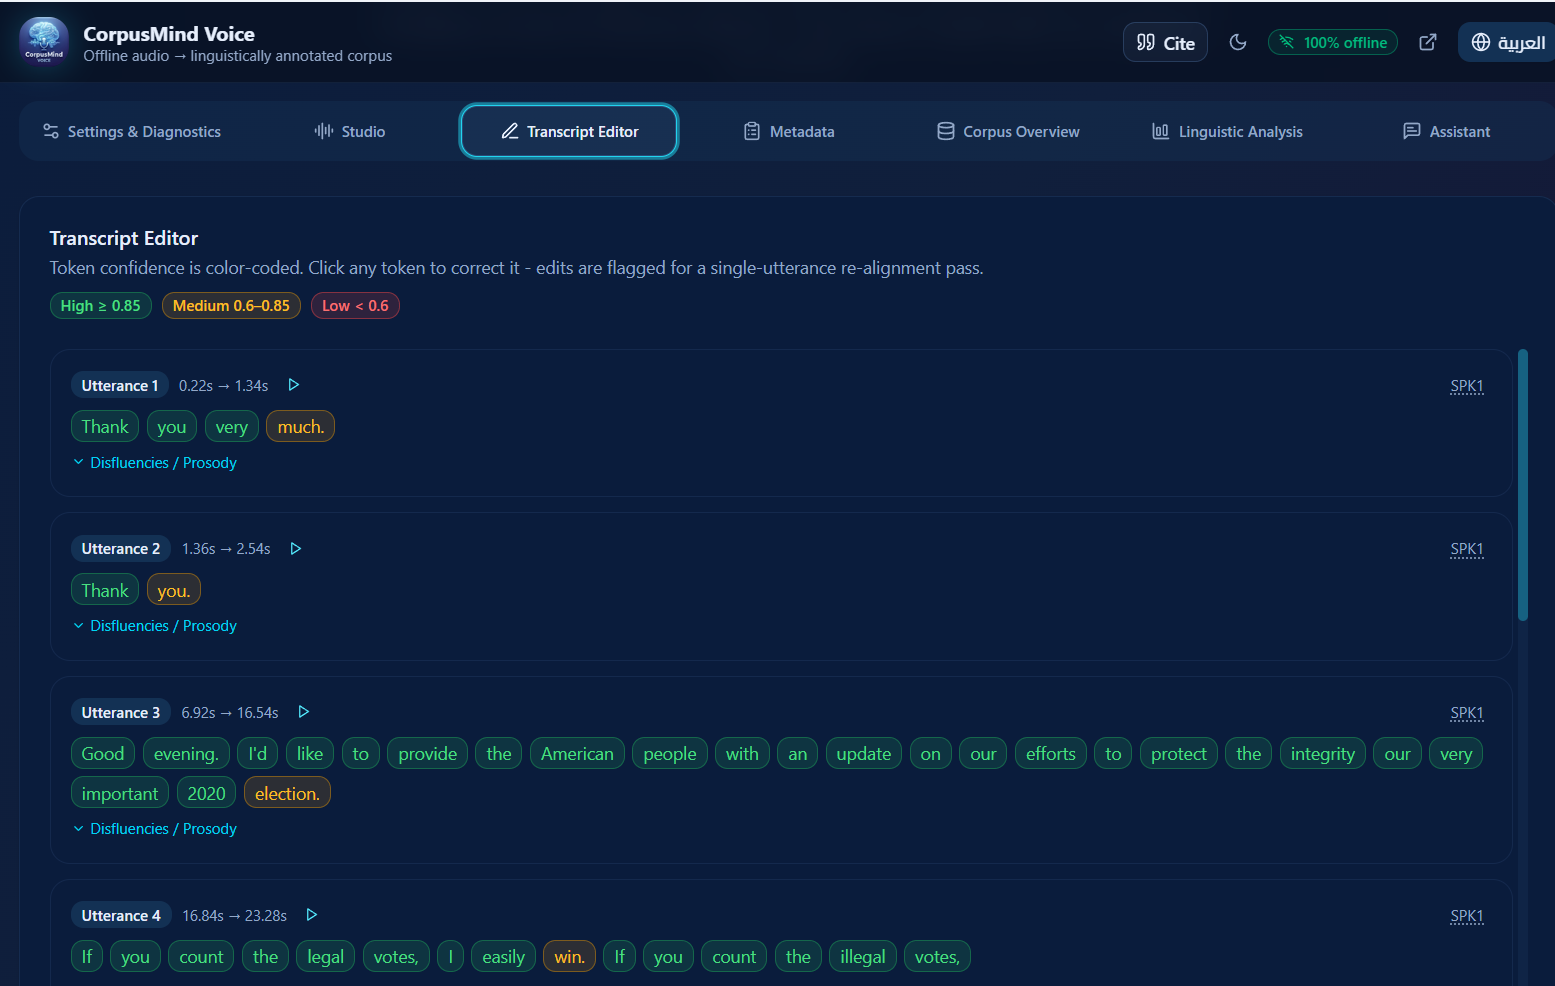
faster-whisper large-v3 (INT8) yields every token with start/end times and a confidence score, colour-coded in the editor: green ≥ 0.85, amber 0.6–0.85, red < 0.6. Correcting a token flags the utterance for a single-utterance re-alignment.
يولّد faster-whisper large-v3 (INT8) كل كلمة مع زمني البداية والنهاية ودرجة ثقة، مُرمّزة بالألوان في المحرر: أخضر ≥ 0.85، وكهرماني 0.6–0.85، وأحمر < 0.6. وتصحيح أي كلمة يضع العبارة في طابور إعادة المحاذاة الفردي.
Phoneme-Grade Forced Alignment
محاذاة قسرية بدقة الصوتونة
Montreal Forced Aligner supplies word and phoneme boundaries to the millisecond, using the Arabic MFA acoustic model and dictionary alongside English US ARPA.
يوفر Montreal Forced Aligner حدود الكلمات والصوتونات بدقة المللي ثانية، بالنموذج الصوتي والقاموس العربيين MFA إلى جانب النموذج الإنجليزي US ARPA.
Praat-Grade Prosody
سمات تنغيمية بدقة Praat
Fundamental frequency (50–400 Hz), intensity, jitter, shimmer and harmonics-to-noise ratio are extracted per token through Parselmouth, with optional openSMILE eGeMAPS features.
يُستخرج التردد الأساسي (50–400 هرتز) والشدة والتذبذب والرقّة ونسبة التوافقيات إلى الضجيج لكل كلمة عبر Parselmouth، مع سمات eGeMAPS الاختيارية من openSMILE.
Bilingual Disfluency Detection
كشف ثنائي اللغة لعيوب الطلاقة
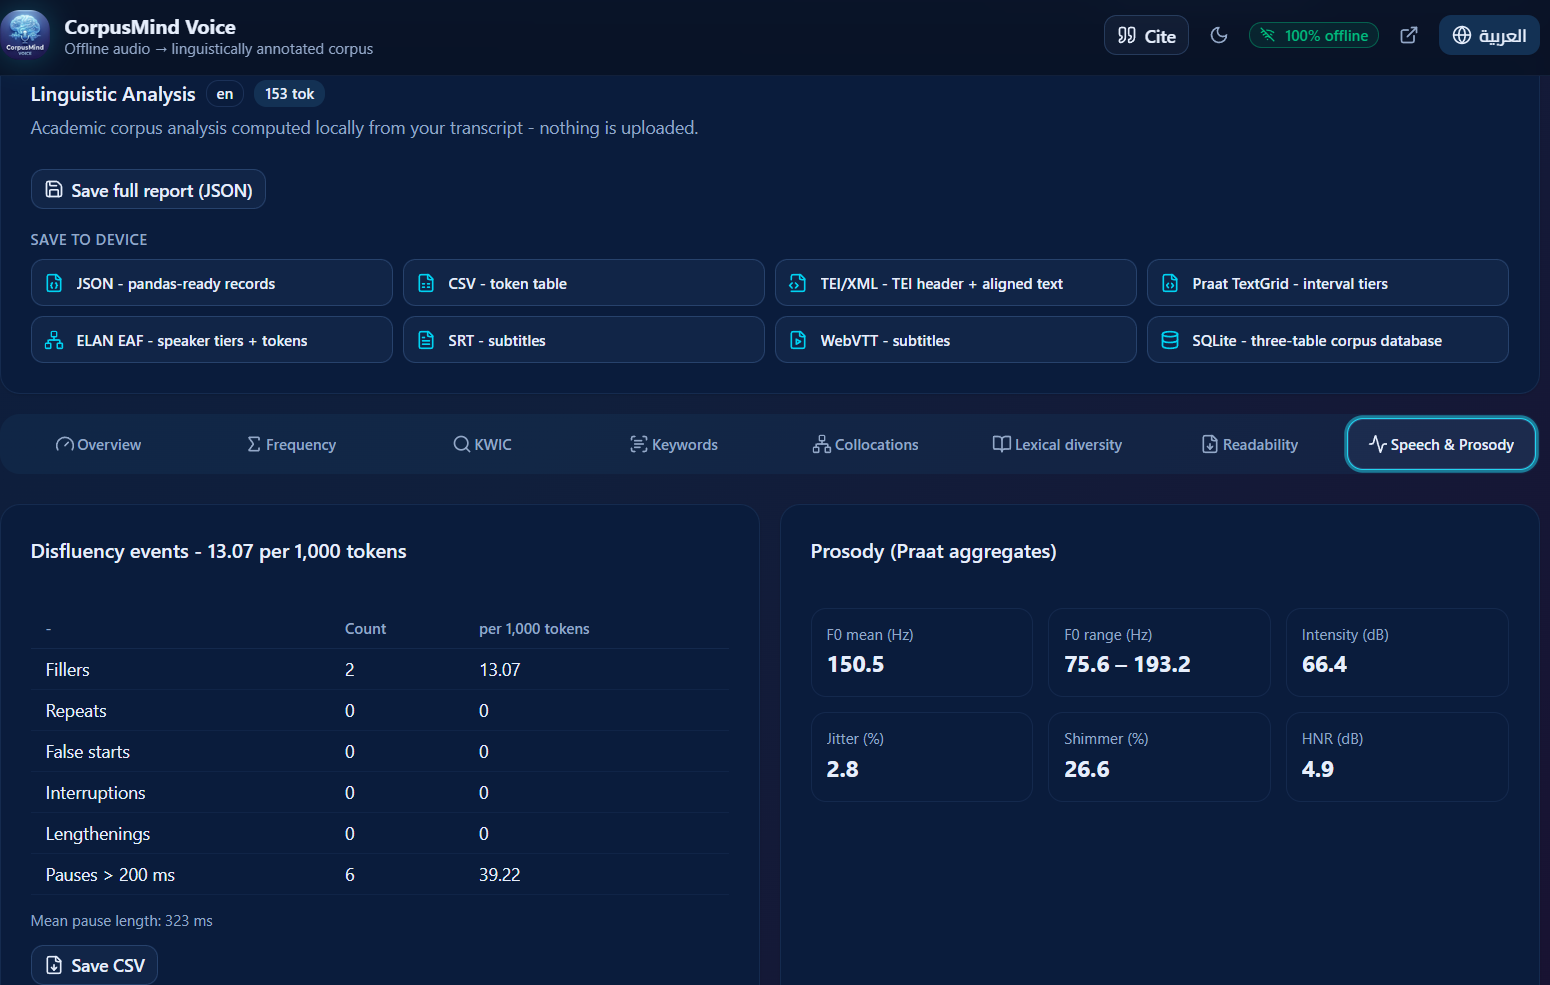
A rule-based scanner annotates pauses longer than 200 ms, fillers (um/uh and يعني/آه/إيه), repeats, false starts, interruptions and lengthenings, the raw material of natural spoken discourse.
يشرِح ماسح قائم على القواعد التوقفات الأطول من 200 مللي ثانية، وحشوات التردد (um/uh ويعني/آه/إيه)، والتكرارات، والبدايات الفاشلة، والمقاطعات، والإطالات، وهي مواد الخطاب المنطوق الطبيعي الخام.
Academic Analysis Suite
حقيبة التحليل الأكاديمي
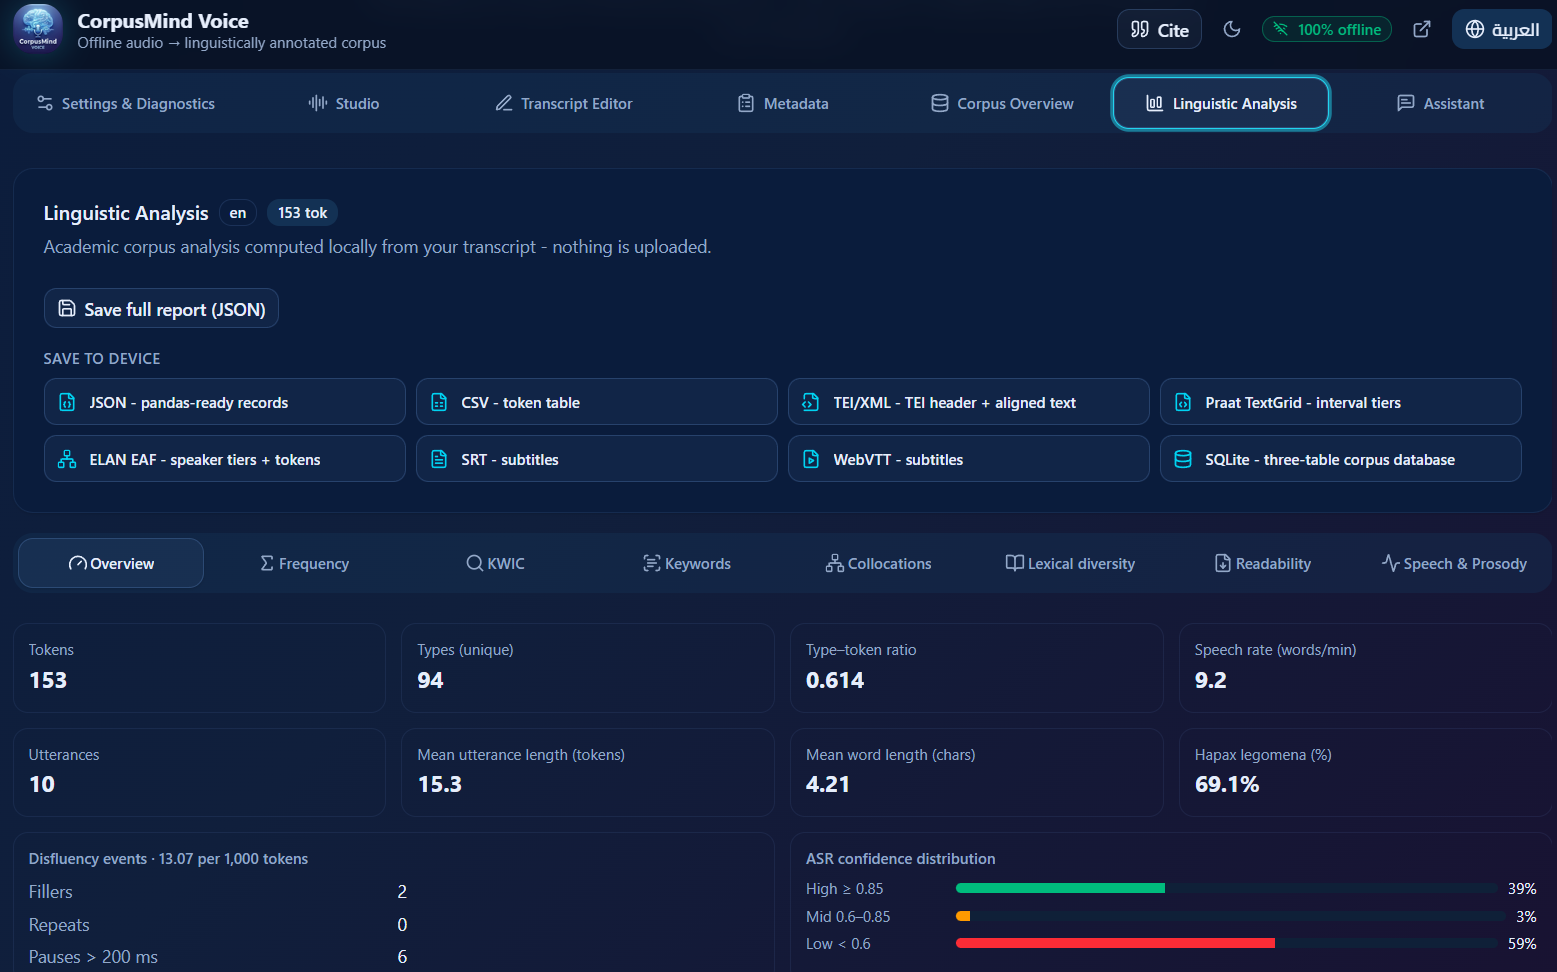
A dedicated Linguistic Analysis tab computes frequency lists with DP dispersion, KWIC concordances with normalized, whole-word and regex matching, keyword detection (log-likelihood G², LogRatio and the %DIFF effect size), collocations (MI, t-score, logDice) and n-grams, Zipf rank-frequency curves, lexical diversity (TTR, MATTR, MTLD), readability (Flesch, Flesch–Kincaid, LIX) and disfluency/prosody rates, every table exportable to CSV, wholly offline.
تبويب مخصص للتحليل اللغوي يحسب قوائم التكرار مع توزّع DP، والكونكوردانس KWIC بأنماط المطابقة الطبيعية والكلمة الكاملة والتعبيرات النمطية، والكلمات المفاتيح (اللوغاريتم الاحتمالي G² وLogRatio ومقياس %DIFF)، والتجمّعات (MI وt-score وlogDice) والمتتاليات، ومنحنى Zipf للرتبة والتكرار، والثراء اللغوي (TTR وMATTR وMTLD)، وسهولة القراءة (فليش وفليش–كينكايد وLIX)، ومعدلات الاضطراب والإيقاع، وكل جدول قابل للحفظ بصيغة CSV، ودون اتصال كليًا.
Cross-Session Corpus Tab
تبويب المجموعة عبر الجلسات
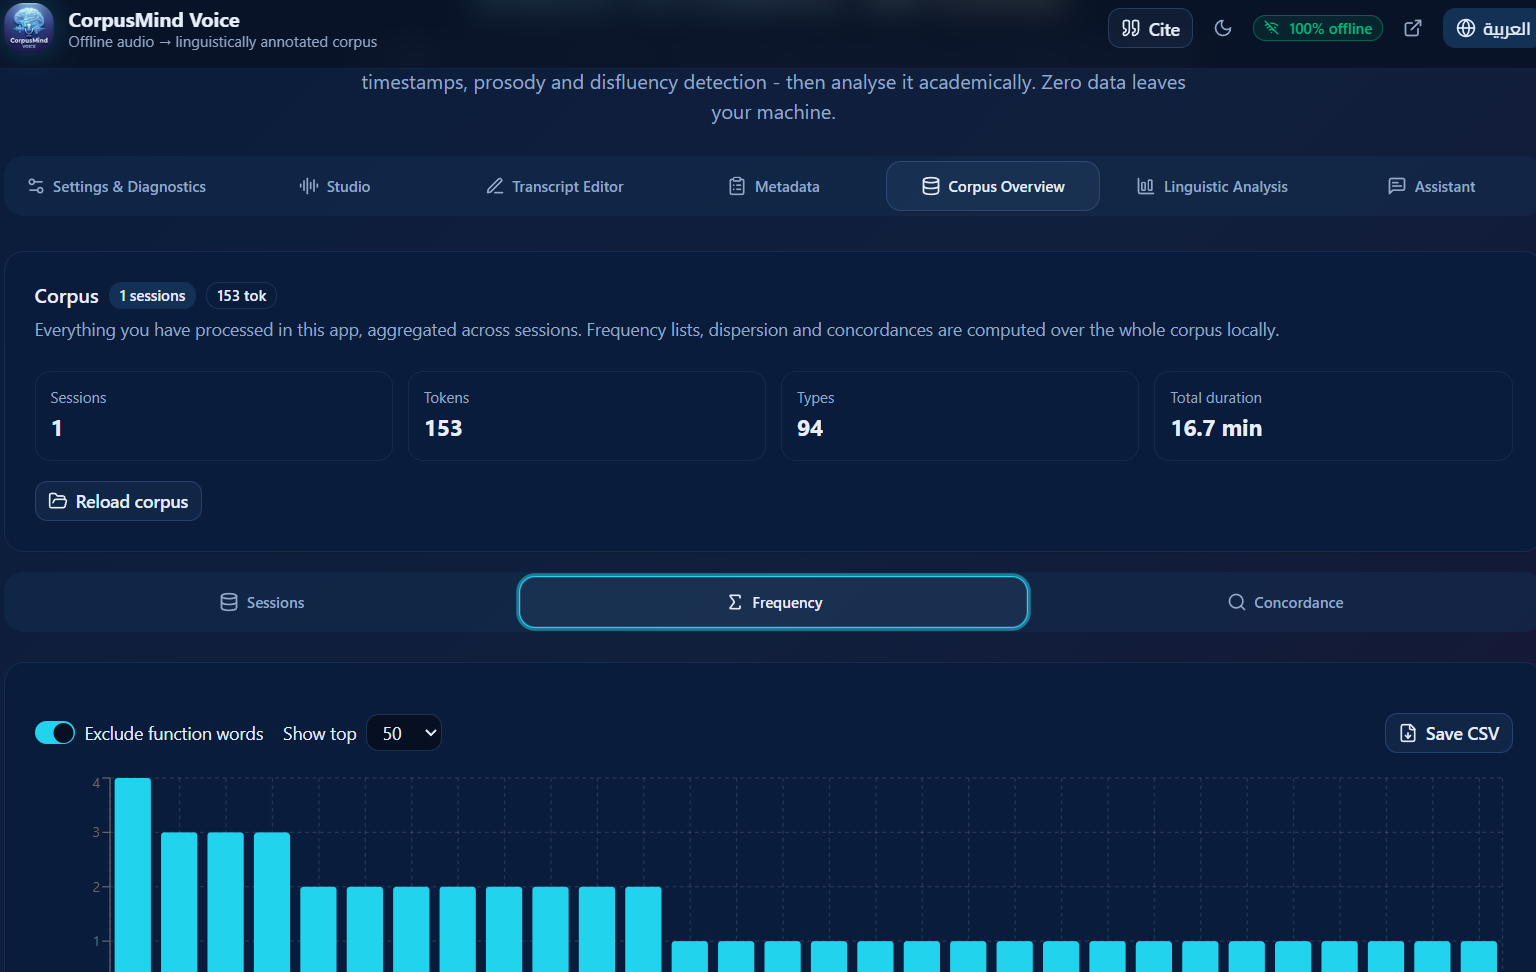
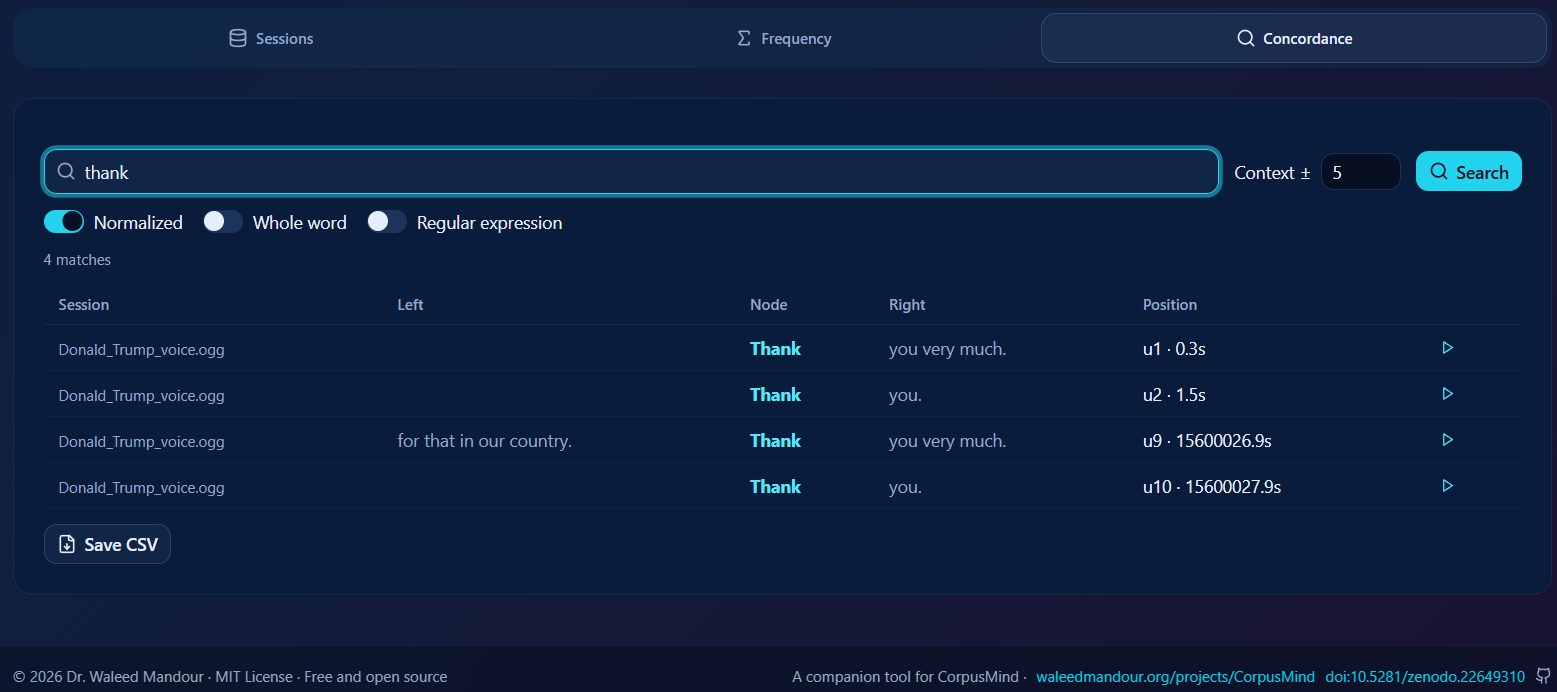
A corpus-wide view aggregates everything processed so far: a sessions inventory with language, duration and token counts, corpus frequency with DP dispersion measured across sessions (0 = evenly spread, 1 = concentrated in one session), and cross-session KWIC concordance where every hit plays the audio around the match.
يعرض تبويب المجموعة كل ما عولج في مكان واحد: جرد جلسات باللغة والمدة وأعداد الكلمات، وتكرار على مستوى المجموعة مع توزّع DP مقيسًا عبر الجلسات (0 = توزّع متساوٍ، 1 = تركّز في جلسة واحدة)، وكونكوردانس KWIC عابر للجلسات يشغّل الصوت حول كل نتيجة.
Light & Dark, On-Device Models
مظهر فاتح وداكن، ونماذج على جهازك
A Light/Dark/System theme follows your OS, and a three-page bilingual Welcome tour introduces the app on first launch. Whisper models from tiny to large-v3 download once inside Settings, persist in the app's private folder and are reused offline: resumable, deletable, yours.
مظهر فاتح/داكن/حسب النظام يتبع إعداد جهازك، وجولة ترحيب ثنائية اللغة من ثلاث صفحات في أول تشغيل. ونماذج Whisper من tiny إلى large-v3 تُنزَّل مرة واحدة من الإعدادات وتبقى في مجلد التطبيق الخاص وتُعاد الاستفادة منها دون اتصال، قابلة للاستئناف والحذف وملك لك.
One-Click CorpusMind Handoff
تسليم بنقرة واحدة إلى كوربَس مايند
A built-in launcher detects a local CorpusMind installation and hands your annotated corpus straight to the analysis environment. Corpus metadata you enter is embedded in the TEI <teiHeader> of every export.
يكشف المشغّل المدمج وجود نسخة محلية من كوربَس مايند ويسلّم مجموعتك المشروحة مباشرة إلى بيئة التحليل. وتُضمَّن البيانات الوصفية التي تُدخلها في وسم <teiHeader> بكل عملية تصدير بصيغة TEI.
Local LLM Assistant
مساعد ذكي محلي
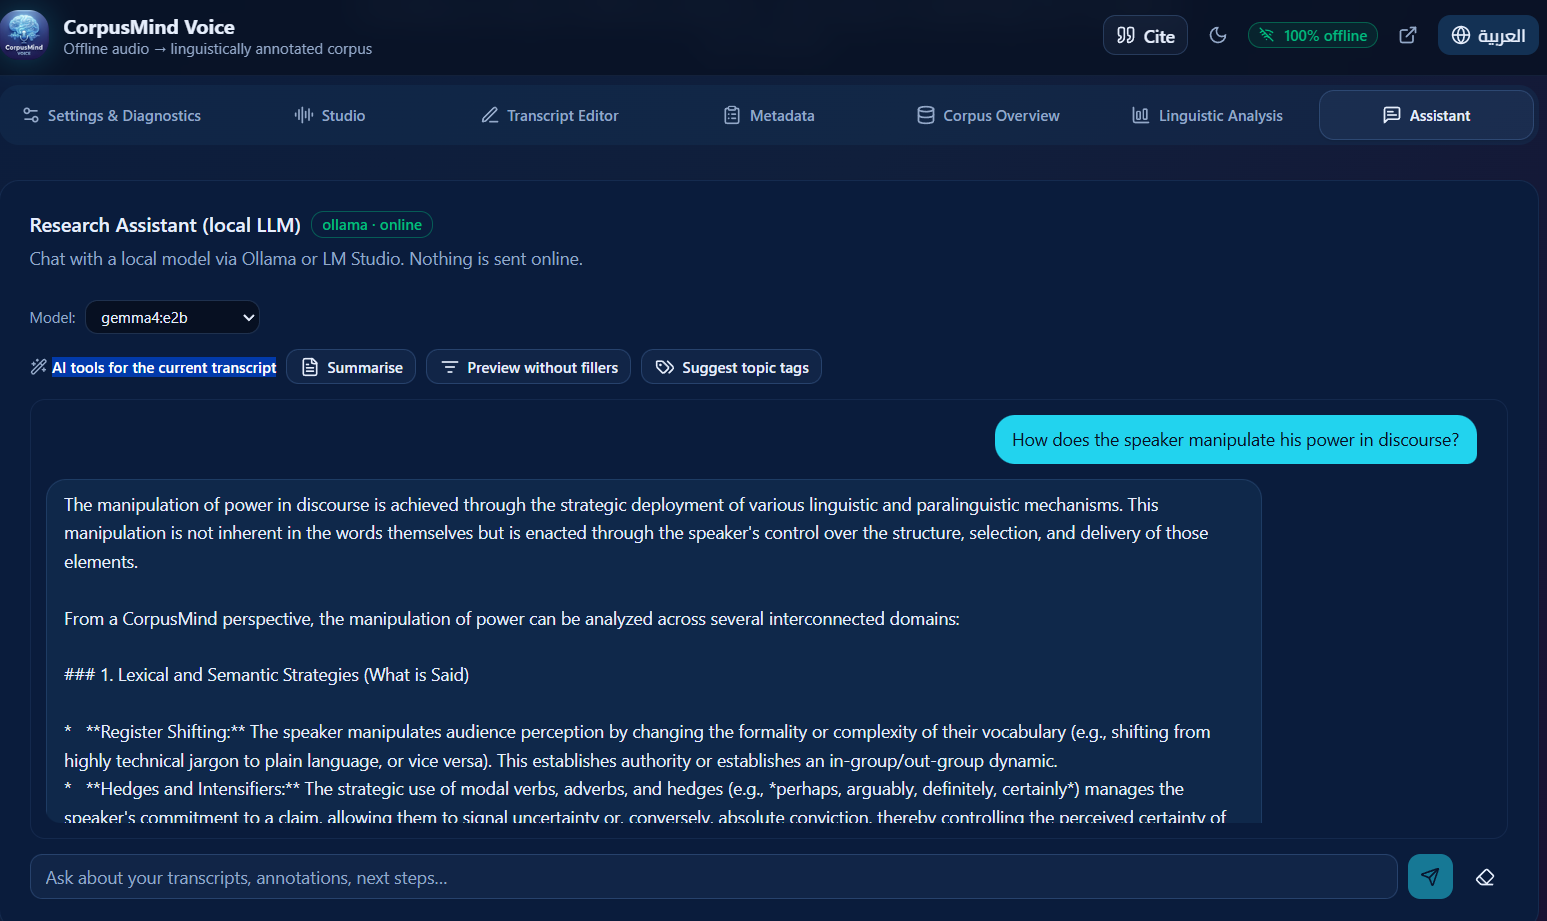
Ollama and LM Studio are detected automatically (with one-click ollama serve startup on desktop). Chat about your corpus, summarise transcripts, preview them without fillers, or suggest topic tags: every call stays on your machine, never a cloud API.
يُكتشف Ollama وLM Studio تلقائيًا (مع تشغيل ollama serve بنقرة واحدة على سطح المكتب). حاور نموذجك عن المجموعة، ولخِّص التفريغات، وعاينها دون حشو، واقترح وسومًا موضوعية: كل الاستدعاءات تبقى على جهازك ولا تواجه سحابة أبدًا.
Installable Mobile PWA
تطبيق ويب تقدمي قابل للتثبيت
Install CorpusMind Voice on iOS or Android straight from the browser and carry the whole pipeline in your pocket: record and analyse on the phone, offline. See the mobile section below.
ثبّت كوربَس مايند فويس على آيفون أو أندرويد مباشرة من المتصفح واحمل خط المعالجة كله في جيبك: سجّل وحلّل على الهاتف ودون اتصال. انظر قسم الأجهزة المحمولة أدناه.
The Six-Stage Pipeline
خط المعالجة من ست مراحل
Each stage is a local process with visible progress, and every stage writes structured records you can audit. كل مرحلة عملية محلية بتقدّم مرئي، وكل مرحلة تكتب سجلات منظّمة قابلة للتدقيق.
Ingest
الاستيعاب
Any container decoded to 16 kHz mono PCM through PyAV, pydub and ffmpeg, with no pre-conversion chores.
فك ترميز أي صيغة إلى PCM أحادي القناة بتردد 16 kHz عبر PyAV وpydub وffmpeg دون خطوات تحويل مسبقة.
Speech Recognition
التعرف على الكلام
faster-whisper large-v3 (INT8) transcribes with word-level timestamps and confidence; models download once, on first run, with a progress bar.
ينسخ faster-whisper large-v3 (INT8) الكلام بطوابع زمنية لكلمة بكلمة ودرجات ثقة؛ وتُنزَّل النماذج مرة واحدة عند التشغيل الأول مع شريط تقدم.
Forced Alignment
المحاذاة القسرية
Montreal Forced Aligner returns word and phoneme boundaries in milliseconds (Arabic MFA + English US ARPA dictionaries).
يعيد Montreal Forced Aligner حدود الكلمات والصوتونات بالمللي ثانية (قاموسا العربية MFA والإنجليزية US ARPA).
Prosody
التنغيم
Parselmouth (Praat) measures F0 (50–400 Hz), intensity, jitter, shimmer and HNR per token; openSMILE eGeMAPS optional.
يقيس Parselmouth (Praat) التردد الأساسي (50–400 هرتز) والشدة والتذبذب والرقّة ونسبة التوافقيات إلى الضجيج لكل كلمة؛ مع خيار openSMILE eGeMAPS.
Disfluency
عيوب الطلاقة
A rule-based scanner flags pauses > 200 ms, bilingual fillers, repeats, false starts, interruptions and lengthenings.
يشير الماسح القاعدي إلى التوقفات > 200 مللي ثانية، والحشوات بلغتين، والتكرارات، والبدايات الفاشلة، والمقاطعات، والإطالات.
Export
التصدير
Structured records land in SQLite, JSON, CSV, TEI P5, Praat TextGrid, ELAN EAF, SRT and WebVTT: ready for CorpusMind, ELAN, Praat, R, Python or your archive.
تُودَع السجلات المنظّمة في SQLite وJSON وCSV وTEI P5 وPraat TextGrid وELAN EAF وSRT وWebVTT: جاهزة لكوربَس مايند أو ELAN أو Praat أو R أو Python أو أرشيفك.
| Format | الصيغة | Contents | المحتويات |
|---|---|---|---|
*.corpusmind.json |
Full records, loads directly with pandas.json_normalize(..., record_path="tokens") |
سجلات كاملة، تُحمَّل مباشرة عبر pandas.json_normalize(..., record_path="tokens") |
|
*.tokens.csv |
Flat token table: index, text, start/end ms, confidence, edited flags | جدول كلمات مسطّح: الرقم، النص، زمنا البداية والنهاية بالمللي ثانية، الثقة، علم التحرير | |
*.tei.xml |
TEI P5: <teiHeader> with your corpus metadata and time-aligned <w> elements |
TEI P5: وسم <teiHeader> مع بياناتك الوصفية وعناصر <w> مضبوطة زمنيًا |
|
*.TextGrid |
Praat TextGrid: utterance and token interval tiers, opens directly in Praat | Praat TextGrid: طوابق فترات للعبارات والكلمات، يُفتح مباشرة في Praat | |
*.eaf |
ELAN EAF 3.0: per-speaker utterance tiers with token sub-tiers, opens in ELAN | ELAN EAF 3.0: طوابق عبارات لكل متحدث مع طوابق فرعية للكلمات، يُفتح في ELAN | |
*.srt / *.vtt |
SRT and WebVTT subtitles generated from utterance timings for media players and editors | ترجمات SRT وWebVTT مولّدة من توقيتات العبارات لمشغلات الوسائط والمحررات | |
*.sqlite |
Standalone three-table database (audio_metadata, utterances, tokens) |
قاعدة بيانات مستقلة بثلاثة جداول (audio_metadata، utterances، tokens) |
Application Interface
واجهة التطبيق
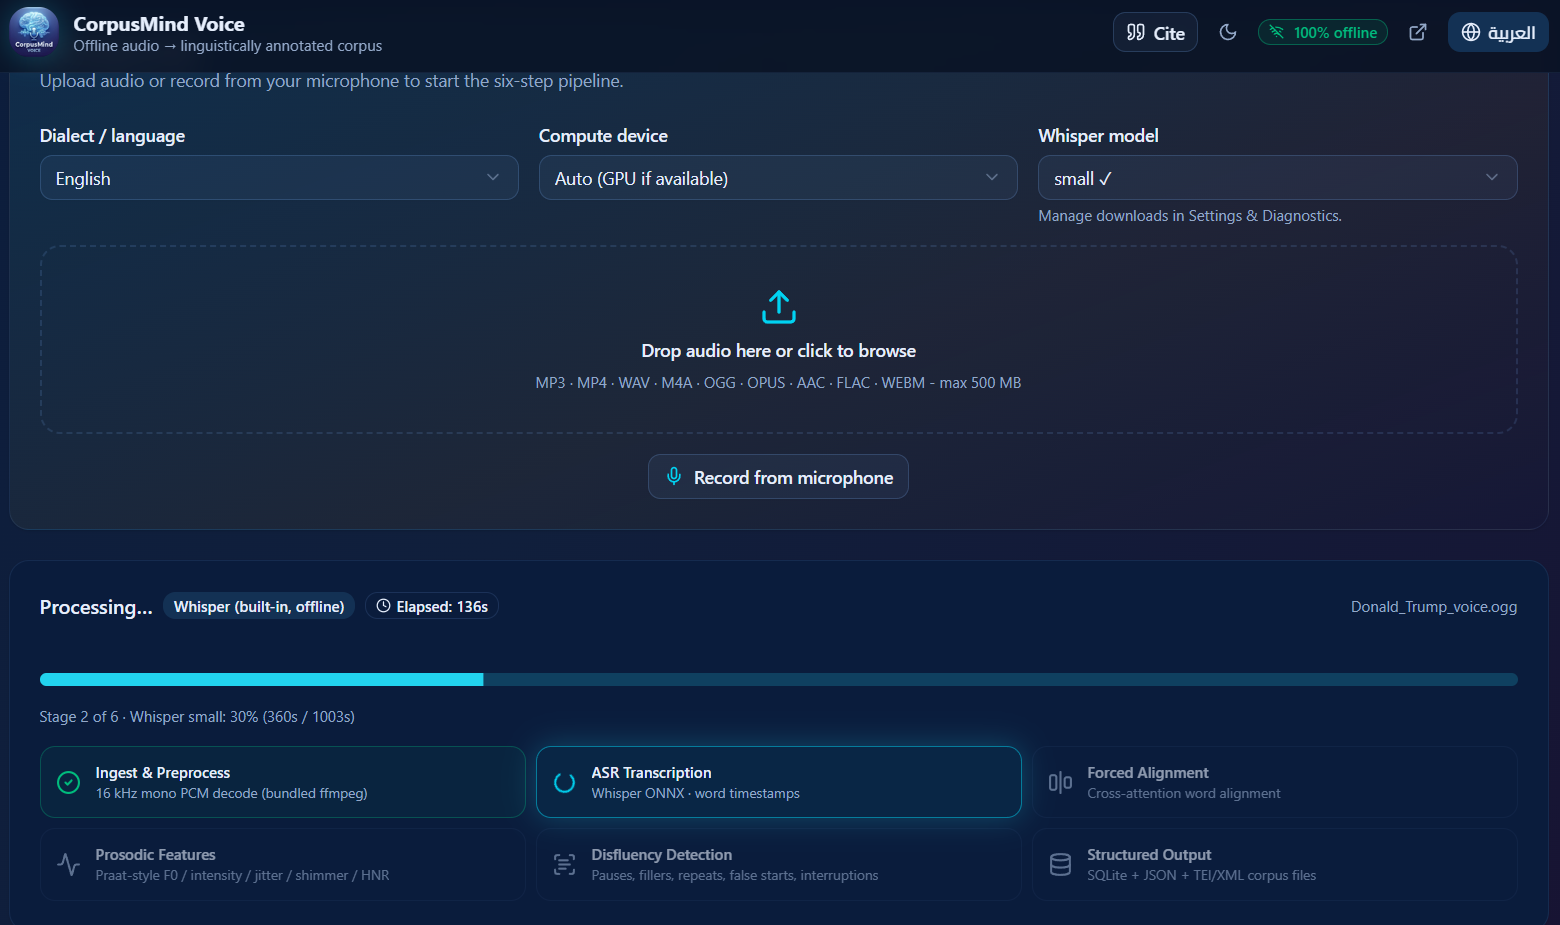
Eight views of the desktop workspace: record or upload audio, follow the six-stage pipeline, polish the transcript with confidence-coded tokens, describe your corpus, then analyse and export it — all computed locally; nothing leaves your machine. Click any slide to open it full-size. ثماني لقطات من مساحة عمل التطبيق: سجّل الصوت أو ارفعه، وتابع خط المعالجة من ست مراحل، وصقح النص بكلمات مرمّزة بمستوى الثقة، وصِف مدوّنتك، ثم حلّلها وصدّرها — كل ذلك محليًا دون أن يغادر شيء جهازك. انقر أي لقطة لعرضها بالحجم الكامل.
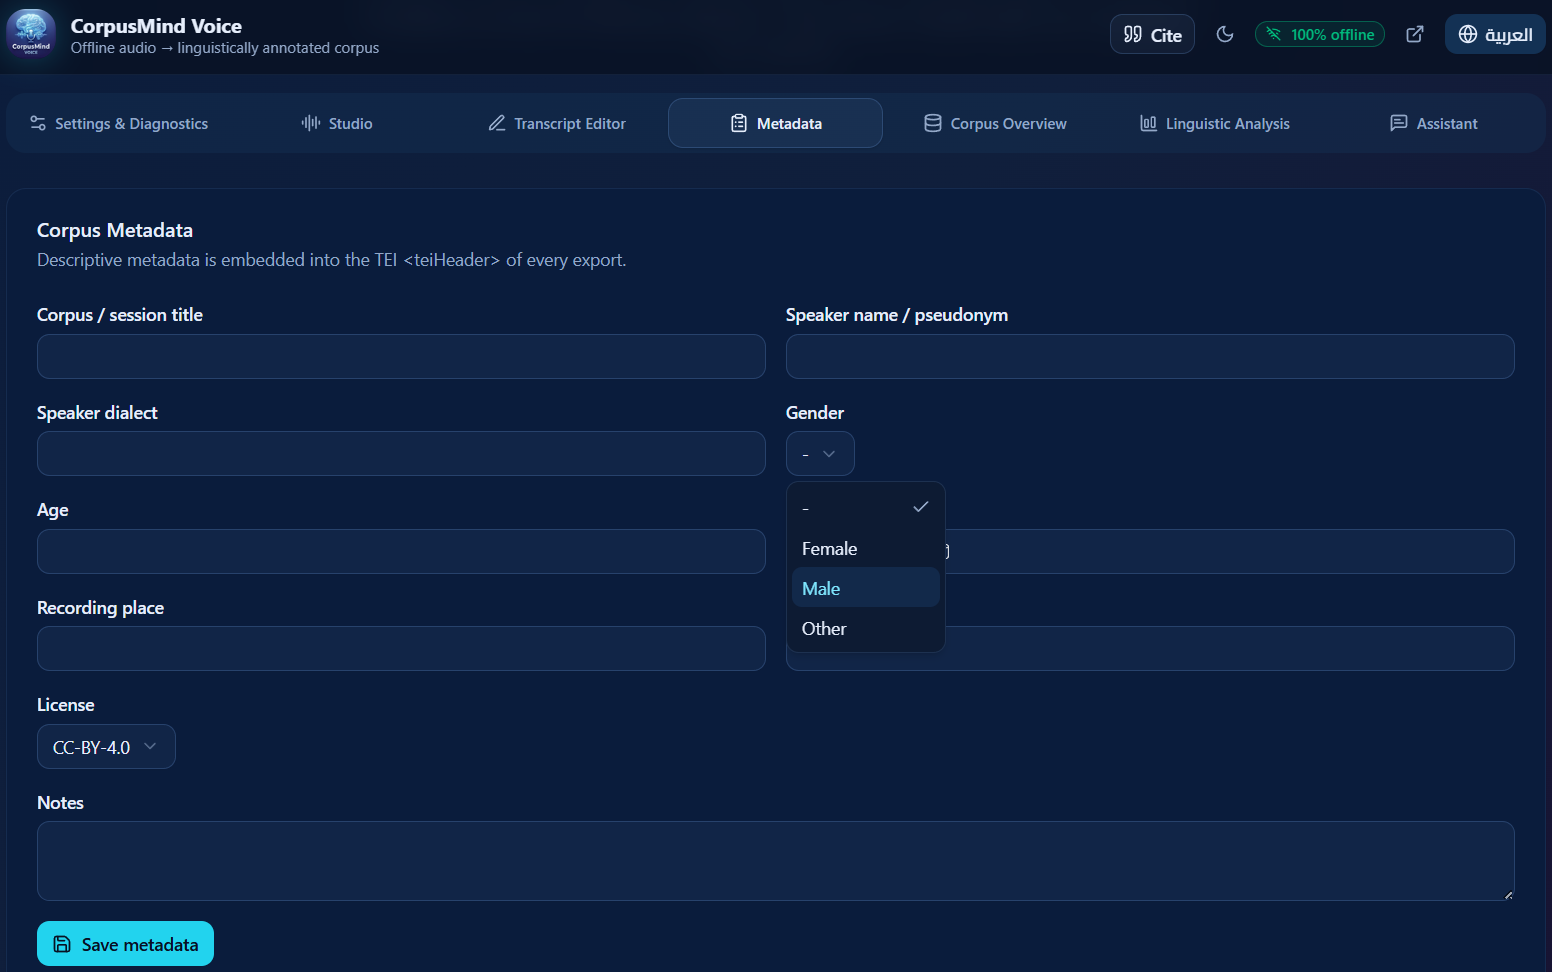
<teiHeader> of every export
البيانات الوصفية — عنوان الجلسة واسم المتحدث المستعار واللهجة والجنس والعمر ومكان التسجيل والرخصة، تُضمَّن في TEI <teiHeader> مع كل تصدير
Research in the Field: CorpusMind Voice on Your Phone
البحث في الميدان: كوربَس مايند فويس على هاتفك
CorpusMind Voice ships as an installable Progressive Web App. On a phone, the researcher can record directly through the microphone and run the same six-stage analysis (recognition, alignment, prosody, disfluency and export) without moving files to a computer first. Once installed, the app shell works offline, so recording and analysis continue in the field, in archives, or anywhere connectivity fails. The recordings, transcripts and metadata stay on the device, which keeps sensitive fieldwork with human participants under the researcher's control at all times. يأتي كوربَس مايند فويس كتطبيق ويب تقدمي قابل للتثبيت. فعلى الهاتف يستطيع الباحث التسجيل مباشرة عبر الميكروفون وتشغيل خط المعالجة نفسه من ست مراحل (التعرف، والمحاذاة، والتنغيم، وعيوب الطلاقة، والتصدير) دون الحاجة إلى نقل الملفات إلى حاسوب أولًا. وبعد التثبيت يعمل هيكل التطبيق دون اتصال، فيستمر التسجيل والتحليل في الميدان أو في الأرشيفات أو في أي مكان تخفق فيه الشبكة. وتبقى التسجيلات والنصوص والبيانات الوصفية على الجهاز، فيبقى العمل الميداني الحساس بمشاركة البشر تحت سيطرة الباحث في كل لحظة.
1 · Install from the Browser
1 · التثبيت من المتصفح
Open corpus-mind-voice.vercel.app on your phone. On iOS: tap Share, then Add to Home Screen. On Android: tap the Install app prompt in the address bar.
افتح corpus-mind-voice.vercel.app على هاتفك. في iOS: انقر مشاركة ثم إضافة إلى الشاشة الرئيسية. وفي أندرويد: انقر خيار تثبيت التطبيق في شريط العنوان.
2 · Record on the Device
2 · التسجيل على الجهاز
Start a session from live microphone input (interviews, elicitation tasks, oral history, lecture excerpts) with no external recorder required.
ابدأ جلسة من مدخل الميكروفون المباشر (مقابلات، أو مهام استثارة لغوية، أو تاريخ شفهي، أو مقاطع محاضرات) دون الحاجة إلى مسجّل خارجي.
3 · Analyse & Export
3 · التحليل والتصدير
Run the full pipeline on the device, review tokens in the confidence-coded editor, then export JSON, CSV, TEI XML, TextGrid, EAF, SRT, WebVTT or SQLite: ready for CorpusMind on your desktop.
شغّل خط المعالجة كاملاً على الجهاز، وراجع الكلمات في المحرر المرمّز بالثقة، ثم صدّر JSON أو CSV أو TEI XML أو TextGrid أو EAF أو SRT أو WebVTT أو SQLite: جاهزة لكوربَس مايند على حاسوبك.
Download CorpusMind Voice
تنزيل كوربَس مايند فويس
Version 1.3.0: free and open source under the MIT License. Desktop bundles run fully offline; the PWA brings the same pipeline to your browser and phone.
الإصدار 1.3.0: مجاني ومفتوح المصدر تحت رخصة MIT. تعمل نسخ سطح المكتب دون اتصال بالكامل؛ ويجلب تطبيق الويب التقدمي خط المعالجة نفسه إلى متصفحك وهاتفك.
What's new in v1.3.0 جديد في الإصدار 1.3.0
- Phone companion: open the desktop app from your phone over Wi-Fi with a pairing QR code; upload and browse, transcribe with the desktop engine, and record from the phone over the https link. رفيق الهاتف: افتح تطبيق سطح المكتب من هاتفك عبر شبكة Wi-Fi برمز اقتران؛ ارفع التسجيلات وتصفّح، وفصّث بمحرك سطح المكتب، وسجّل من الهاتف عبر رابط https.
- Reliable uploads and recordings: app data now lives in the per-user application data folder, so recording and uploading work in every install mode (Program Files included) and older recordings migrate automatically. رفع وتسجيل موثوقان: تُخزَّن بيانات التطبيق الآن في مجلد بيانات المستخدم، فيعمل الرفع والتسجيل في كل أنماط التثبيت (بما في ذلك Program Files)، وتُنقل التسجيلات الأقدم تلقائيًا.
- Ollama anywhere on your network: point the app at an Ollama daemon on another machine, alongside fixes for delete reporting, Windows Python resolution, the stale shell after upgrades and audio playback. Ollama على شبكتك: وجّه التطبيق إلى خدمة Ollama على جهاز آخر، مع إصلاحات للإبلاغ عن الحذف، وحل بايثون على ويندوز، والواجهة القديمة بعد الترقية، وحالة تشغيل الصوت.
- Rebuilt installers (2026-09-12): if you downloaded a desktop installer on 2026-09-11, please re-download it. The first v1.3.0 packaging pass could fail uploads and recordings inside the installed app with "Internal Server Error"; the rebuilt installers fix it. The web/PWA version was never affected. مثبّتات مُعاد بناؤها (١٢-٠٩-٢٠٢٦): إذا نزّلت مثبّت سطح المكتب في ١١-٠٩-٢٠٢٦، فأعد تنزيله. كانت أول حزمة ١٫٣٫٠ قد تُفشل الرفع والتسجيل داخل التطبيق المثبّت بخطأ «Internal Server Error»؛ وقد عالجتها المثبّتات المُعاد بناؤها. نسخة الويب/PWA لم تتأثر.
Version 1.3.0 · MIT License · Release notes
الإصدار 1.3.0 · رخصة MIT · ملاحظات الإصدار
Cite CorpusMind Voice
الاقتباس لكوربَس مايند فويس
If you use CorpusMind Voice in research, teaching, or published work, please cite it using the references below (also available in-app via the Cite button, and in citation.cff). إذا استخدمت كوربَس مايند فويس في بحث أو تدريس أو عمل منشور، فيرجى اقتباسه بالمراجع أدناه (وهي متاحة داخل التطبيق عبر زر اقتباس وفي ملف citation.cff).
The CorpusMind Family
عائلة كوربَس مايند
Parent Application: CorpusMind
تطبيق الأم: كوربَس مايند
The local-first, AI-native research environment for corpus linguistics and multimodal discourse analysis. CorpusMind Voice hands its annotated corpora straight into CorpusMind for concordancing, collocation, and discourse analysis.
بيئة البحث المحلية أولاً والمدعومة بالذكاء الاصطناعي لتحليل اللغة والخطاب متعدد الوسائط. يسلّم كوربَس مايند فويس مجموعاته المشروحة مباشرة إلى كوربَس مايند للكوردانس والمتصاحبات والتحليل الخطابي.
Visit CorpusMind زيارة كوربَس مايندCompanion Application: CorpusMind Lens
التطبيق المرافق: كوربَس مايند لِنز
A separate installable desktop application for vision-LM-powered multimodal discourse analysis: image-set management, visual grammar frameworks, image–text alignment and cross-image batch analysis, connected to the same CorpusMind engine.
تطبيق مكتبي مستقل لتحليل الخطاب متعدد الوسائط المدعوم بنماذج الرؤية اللغوية: إدارة مجموعات الصور، وأطر القواعد البصرية، ومحاذاة الصورة والنص، والتحليل الدفعي عبر الصور، متصل بمحرك كوربَس مايند نفسه.
Visit CorpusMind Lens زيارة كوربَس مايند لِنزLive Statistics
الإحصاءات المباشرة
Downloads by Platform التحميلات حسب المنصة
Data fetched from GitHub Releases API · updates in real time البيانات من واجهة GitHub Releases · تُحدّث في الوقت الفعلي