CorpusMind: The All-in-One Research Environment for Linguists
كوربَس مايند: بيئة بحثية متكاملة للغويين
Dr. Waleed Mandour (Sultan Qaboos University) · Prof. Wesam Ibrahim (Princess Nourah Bint Abdulrahman University) د. وليد مندور (جامعة السلطان قابوس) · أ.د. وسام إبراهيم (جامعة الأميرة نورة بنت عبدالرحمن)
CorpusMind is an integrated research environment that unifies corpus linguistics, multimodal discourse analysis, and AI-assisted interpretation within a single desktop application. It enables a linguist to go from raw texts and images to publication-ready quantitative and qualitative analysis without writing a line of code, without losing methodological transparency, and without the subscription fees of commercial corpus platforms. The platform bundles a FastAPI engine, a Tauri 2 shell, and an installable PWA, supporting English, Arabic, Urdu, Hindi, and Persian text analysis through spaCy, CAMeL Tools, and per-language normalization, fifteen discourse-analysis lenses (seven text, eight vision) grounded in the peer-reviewed literature, a Learner Research suite (CAF battery, Contrastive Interlanguage Analysis, error-pattern candidates), semantic Vector KWIC search powered by multilingual embeddings, CQL-style corpus queries for the concordancer, a pluggable AI assistant that grounds every claim in corpus evidence, a teacher-as-server Student Mode that opens a read-only classroom server for students' phones and tablets with enforced seat limits and an anonymous audit log, and — through the companion CorpusMind Lens app — a multimodal vision pipeline operationalising Kress and van Leeuwen's Visual Grammar. All analytical operations produce YAML provenance records, ensuring that every result is traceable, reproducible, and ready for peer review.
كوربَس مايند بيئة بحثية متكاملة توحّد تحليل اللغة والخطاب متعدد الوسائط والتفسير المدعوم بالذكاء الاصطناعي ضمن تطبيق مكتبي واحد. تُمكّن اللغوي من الانتقال من النصوص والصور الخام إلى تحليل كمي ونوعي جاهز للنشر دون كتابة سطر برمجي واحد، ودون التضحية بالشفافية المنهجية، ودون رسوم اشتراك المنصات التجارية. تجمع المنصة محرك FastAPI وقشرة Tauri 2 وتطبيق ويب تقدمي قابل للتثبيت، وتدعم تحليل النصوص بالإنجليزية والعربية والأردية والهندية والفارسية عبر spaCy وCAMeL Tools والمُطبِّعات الخاصة بكل لغة، وخمس عشرة عدسة لتحليل الخطاب (سبع نصية وثمانية بصرية) مستندة إلى الأدبيات المحكّمة، ومجموعة أبحاث لغة المتعلم (بطارية CAF، والتحليل التقابلي للغة الوسطى، ومؤشرات أنماط الأخطاء)، والبحث السياقي الدلالي (Vector KWIC) المدعوم بالتضمينات متعددة اللغات، واستعلامات مجموعات لغوية بأسلوب CQL لكاشف السياق، ومساعداً ذكياً اصطناعياً قابلاً للتوصيل يؤسّس كل ادعاء بأدلة المجموعة اللغوية، ووضع الطالب بوصف المعلم خادماً يفتح خادم فصل دراسي للقراءة فقط لهواتف الطلاب وأجهزتهم اللوحية مع حدود مقاعد مفروضة وسجل تدقيق مجهول الهوية، و— عبر تطبيق كوربَس مايند لِنز المرافق — خط معالجة بصري متعدد الوسائط يُفعّل قواعد الصورة المرئية لكريس وفان ليوفان. تُنتج جميع العمليات التحليلية سجلات إثبات بصيغة YAML، مما يضمن إمكانية تتبع كل نتيجة وإعادة إنتاجها وجاهزيتها للتحكيم العلمي.
Application Interface
واجهة التطبيق
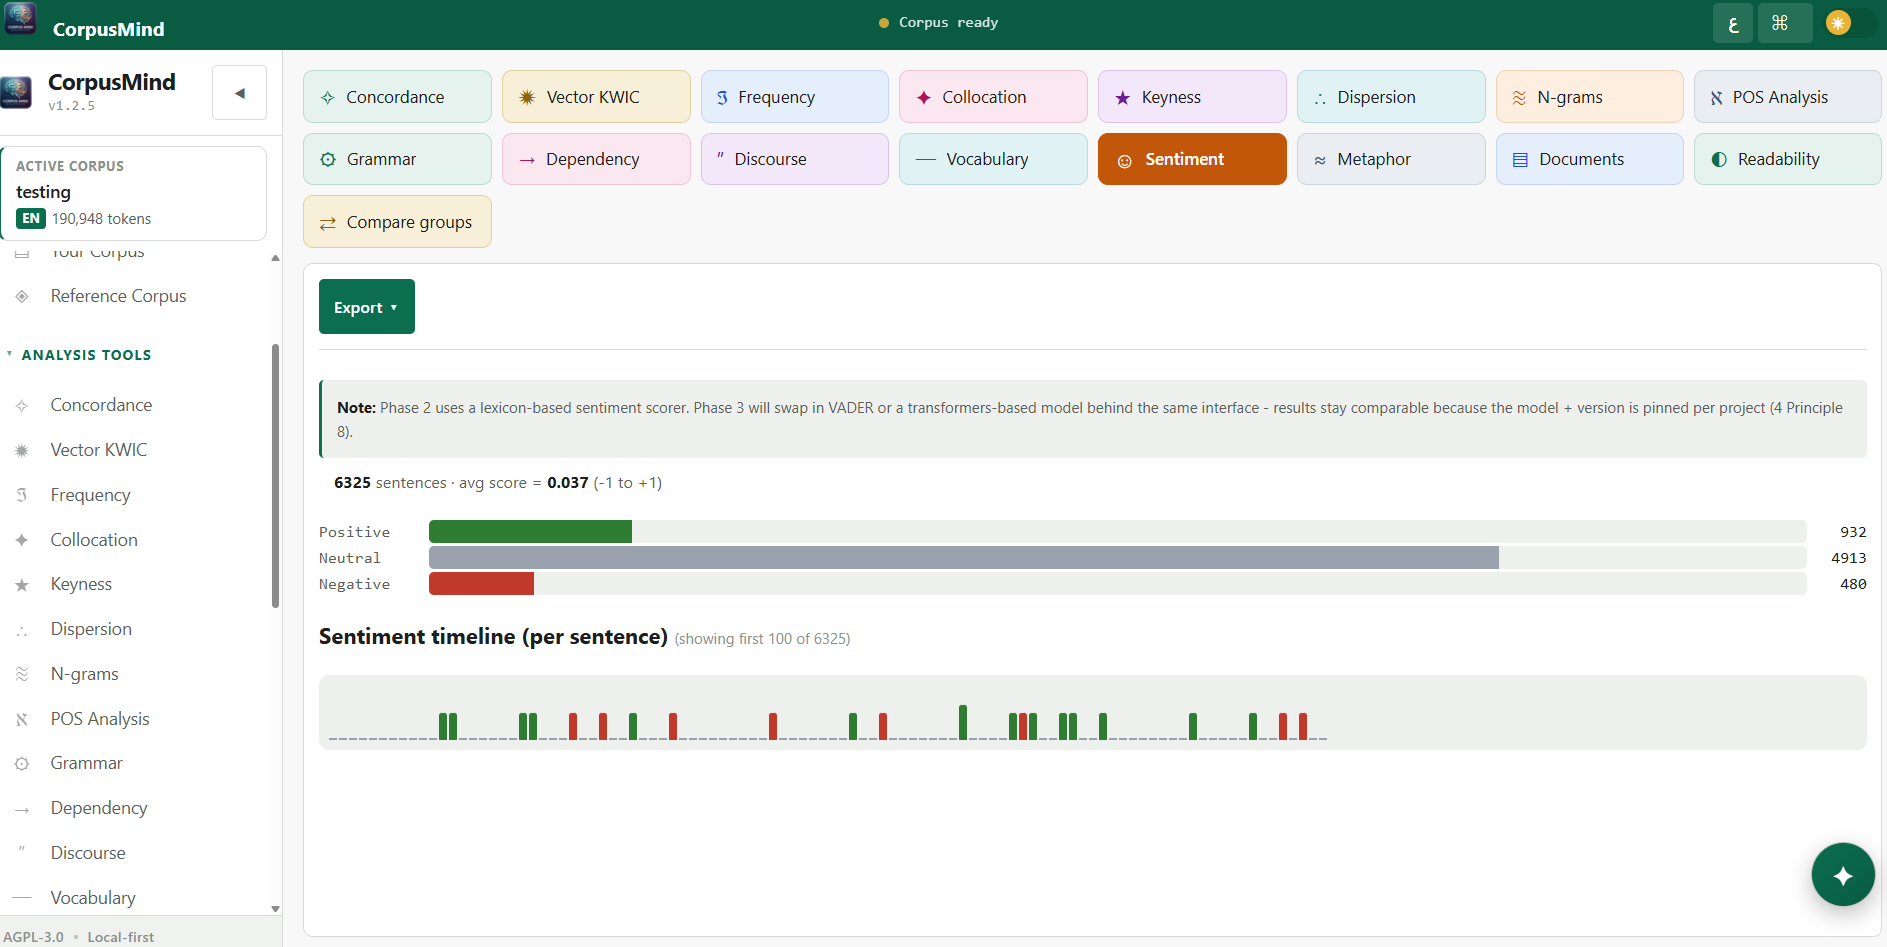
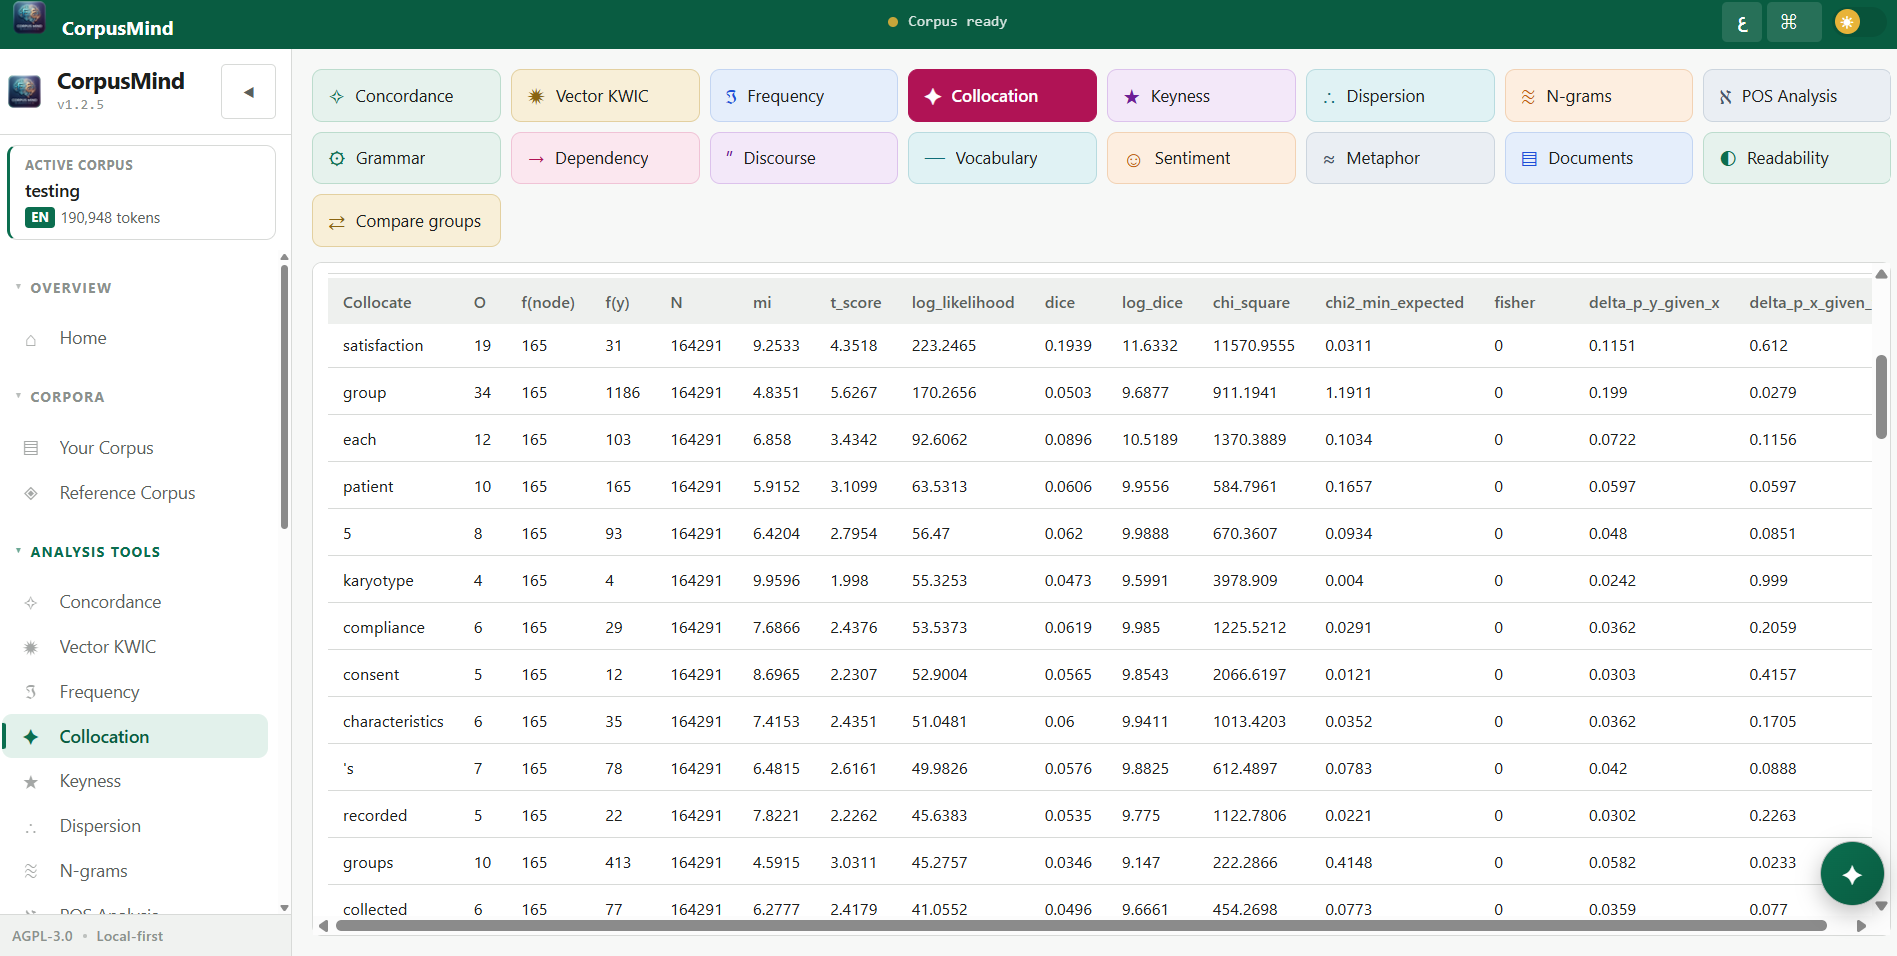
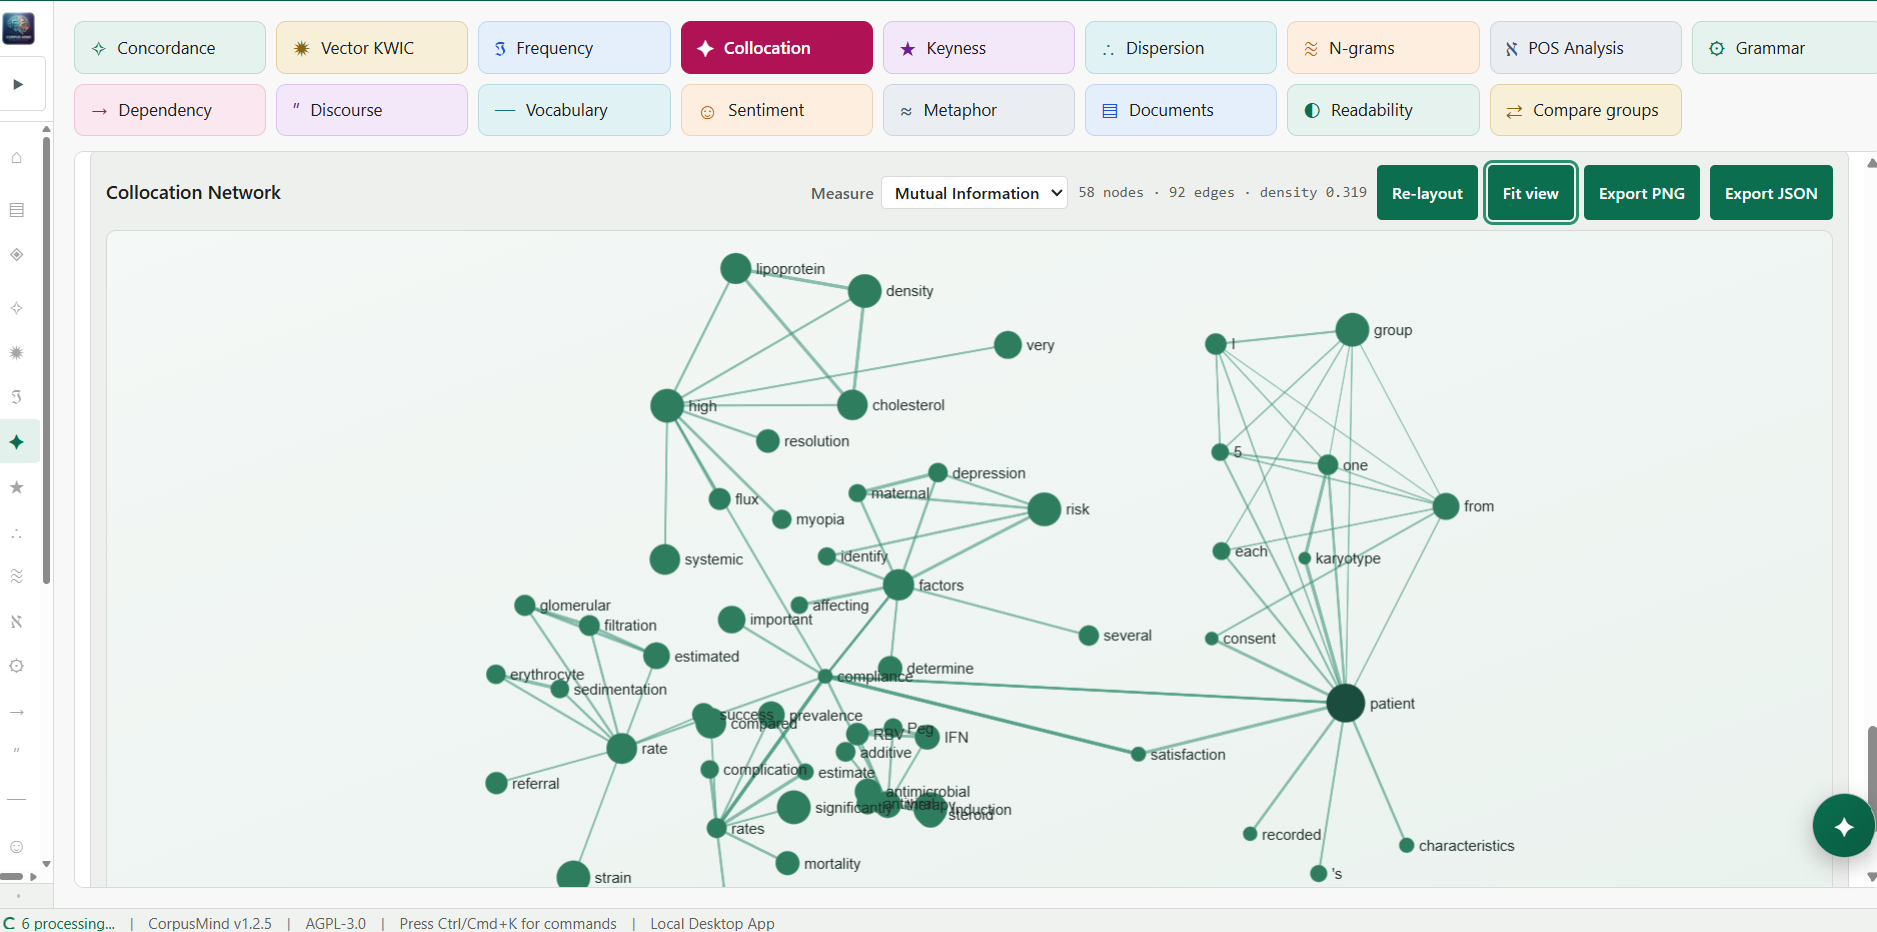
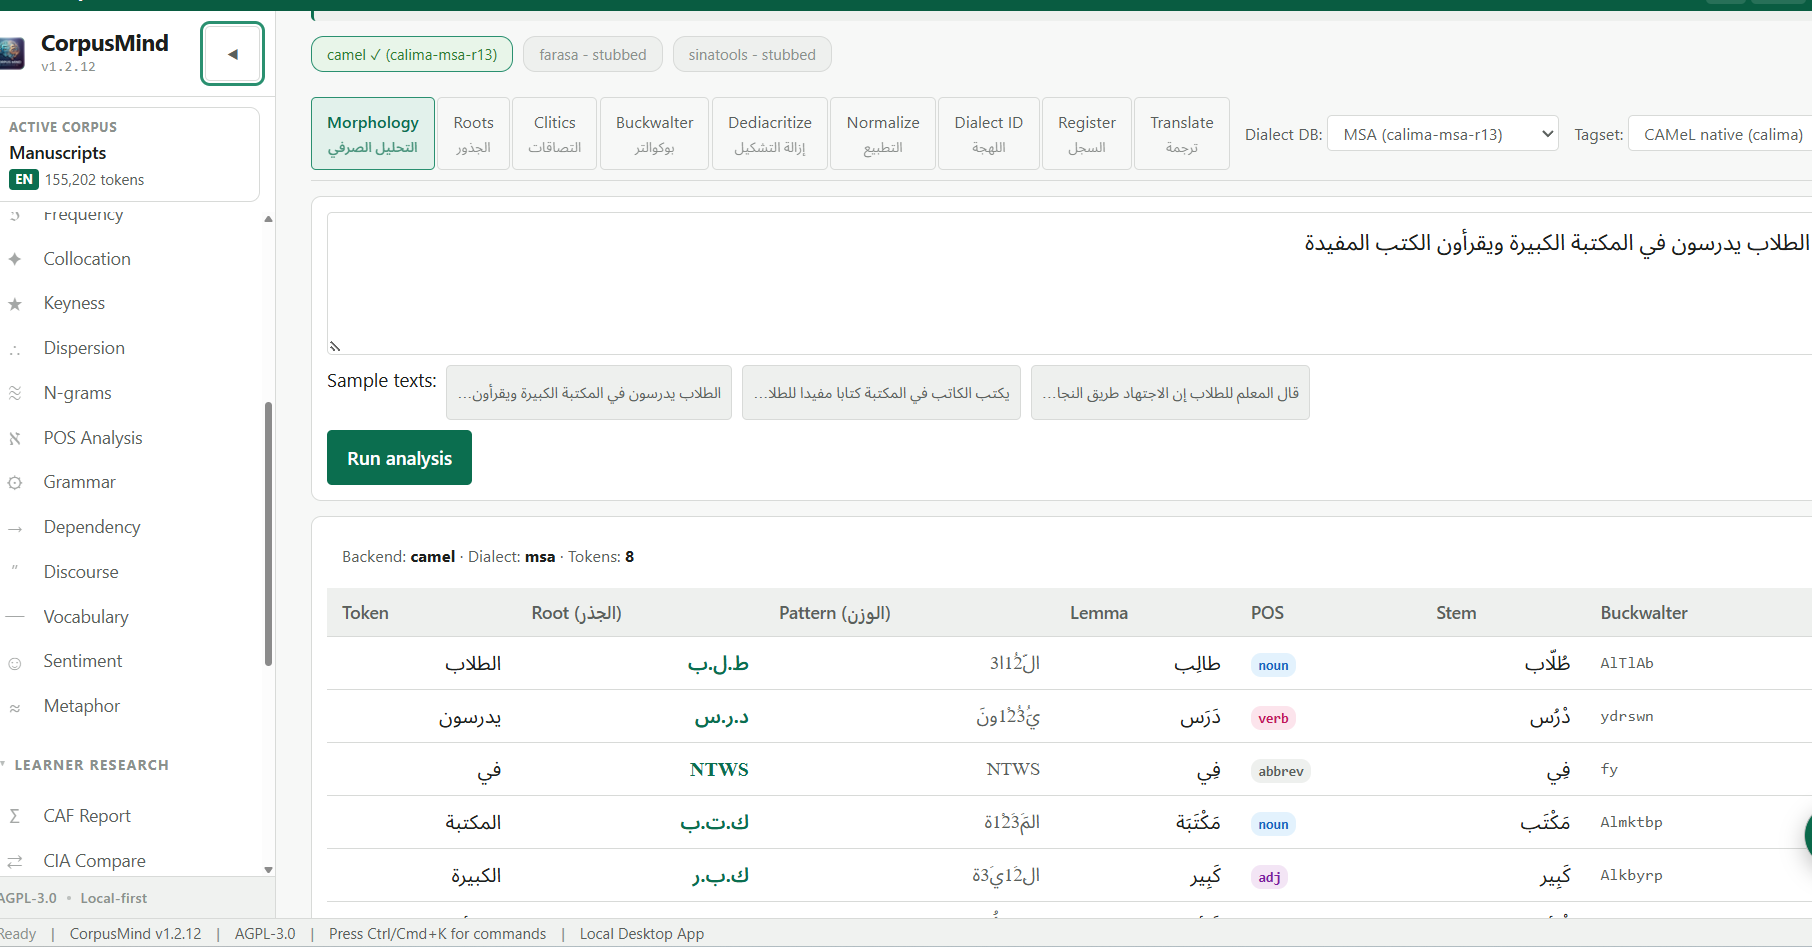
A ribbon-style workspace with suite-based navigation — corpus analysis, Learner Research, Arabic tools, and the AI assistant — plus a command palette, full RTL support for Arabic, and dark / light themes. مساحة عمل بشريط تنقل قائم على المجموعات — تحليل المجموعات اللغوية، وأبحاث لغة المتعلم، وأدوات العربية، والمساعد الذكي — مع لوحة أوامر، ودعم كامل للعربية RTL، ووضعين داكن وفاتح.
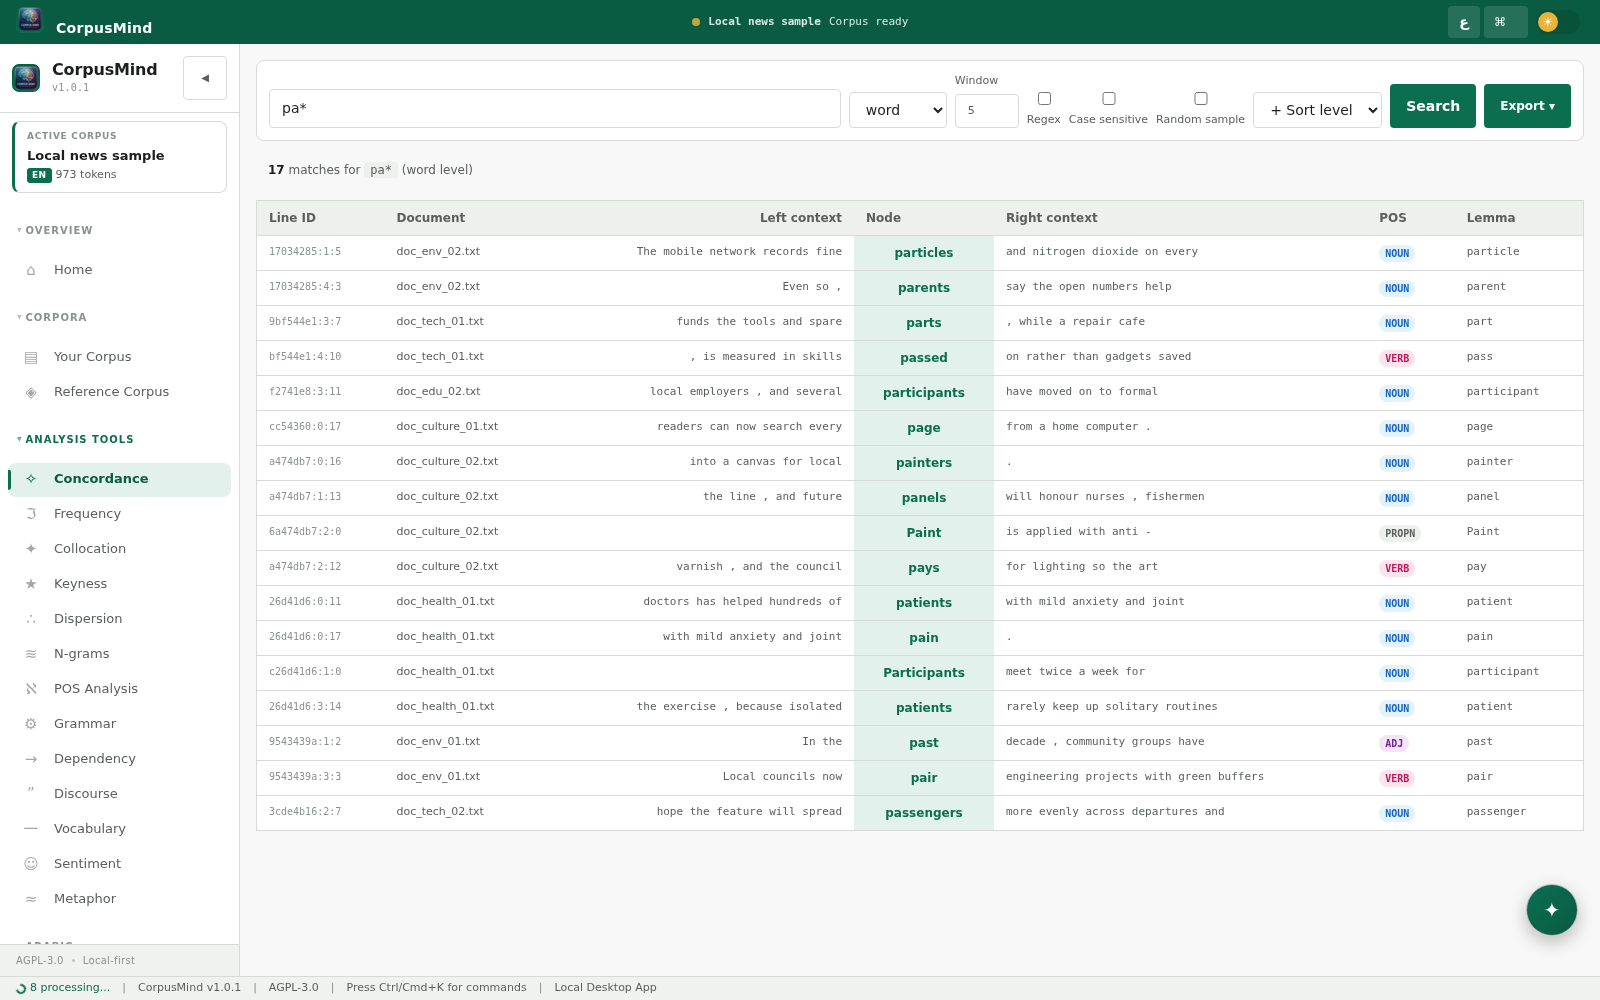
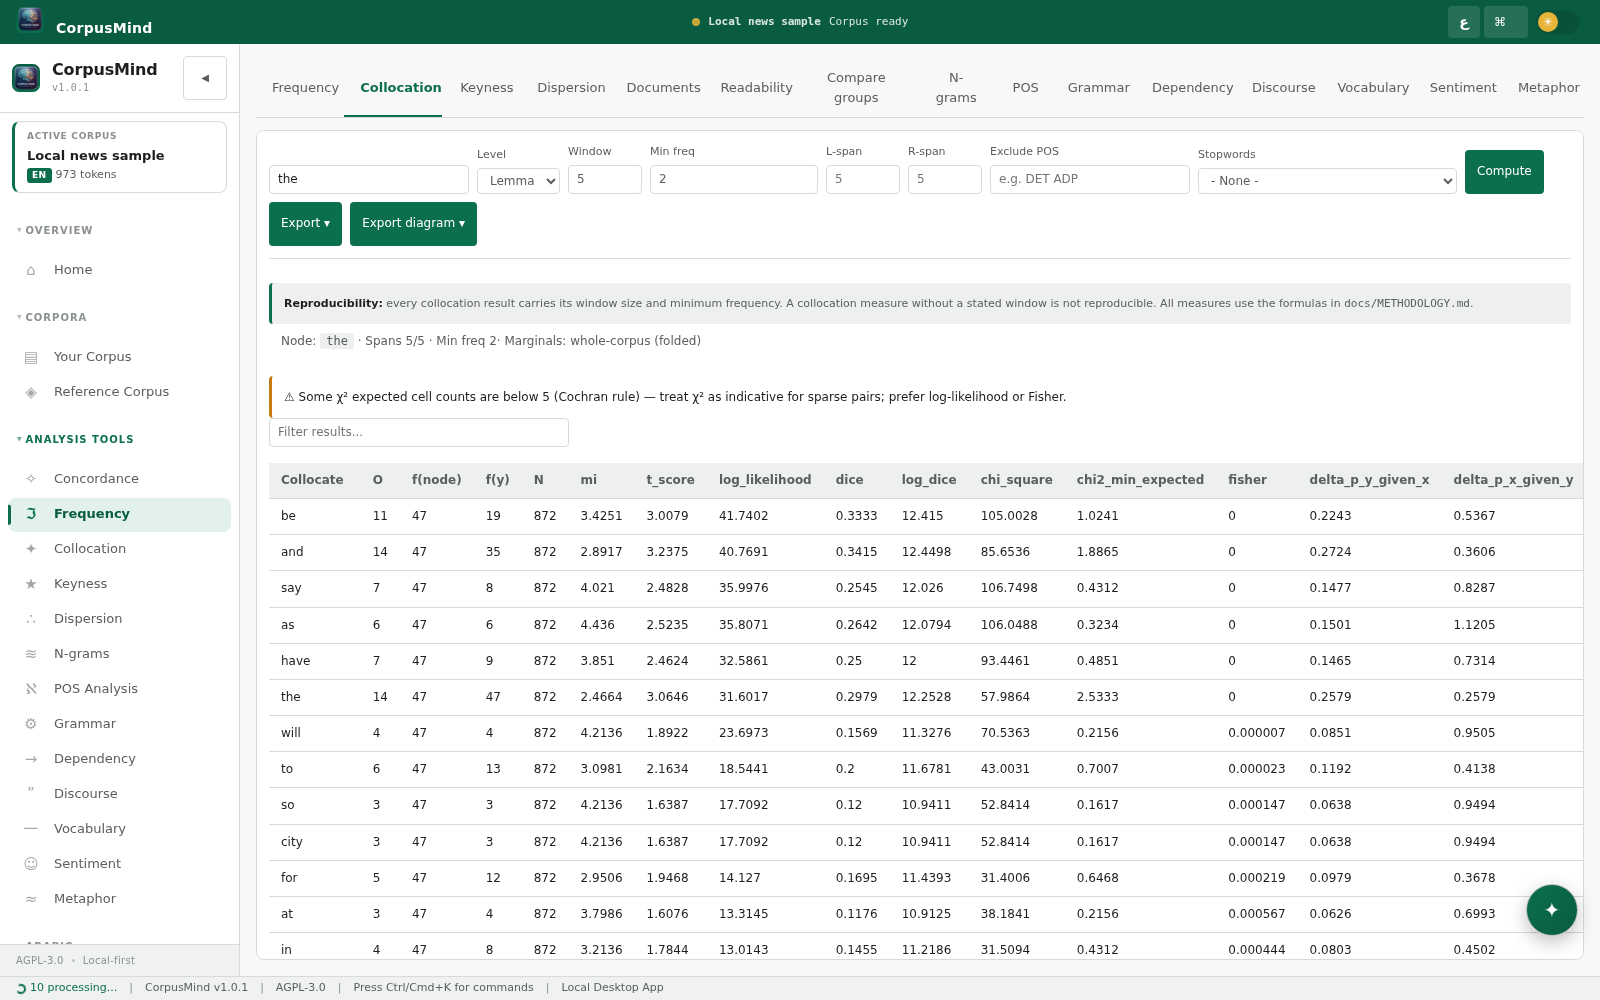
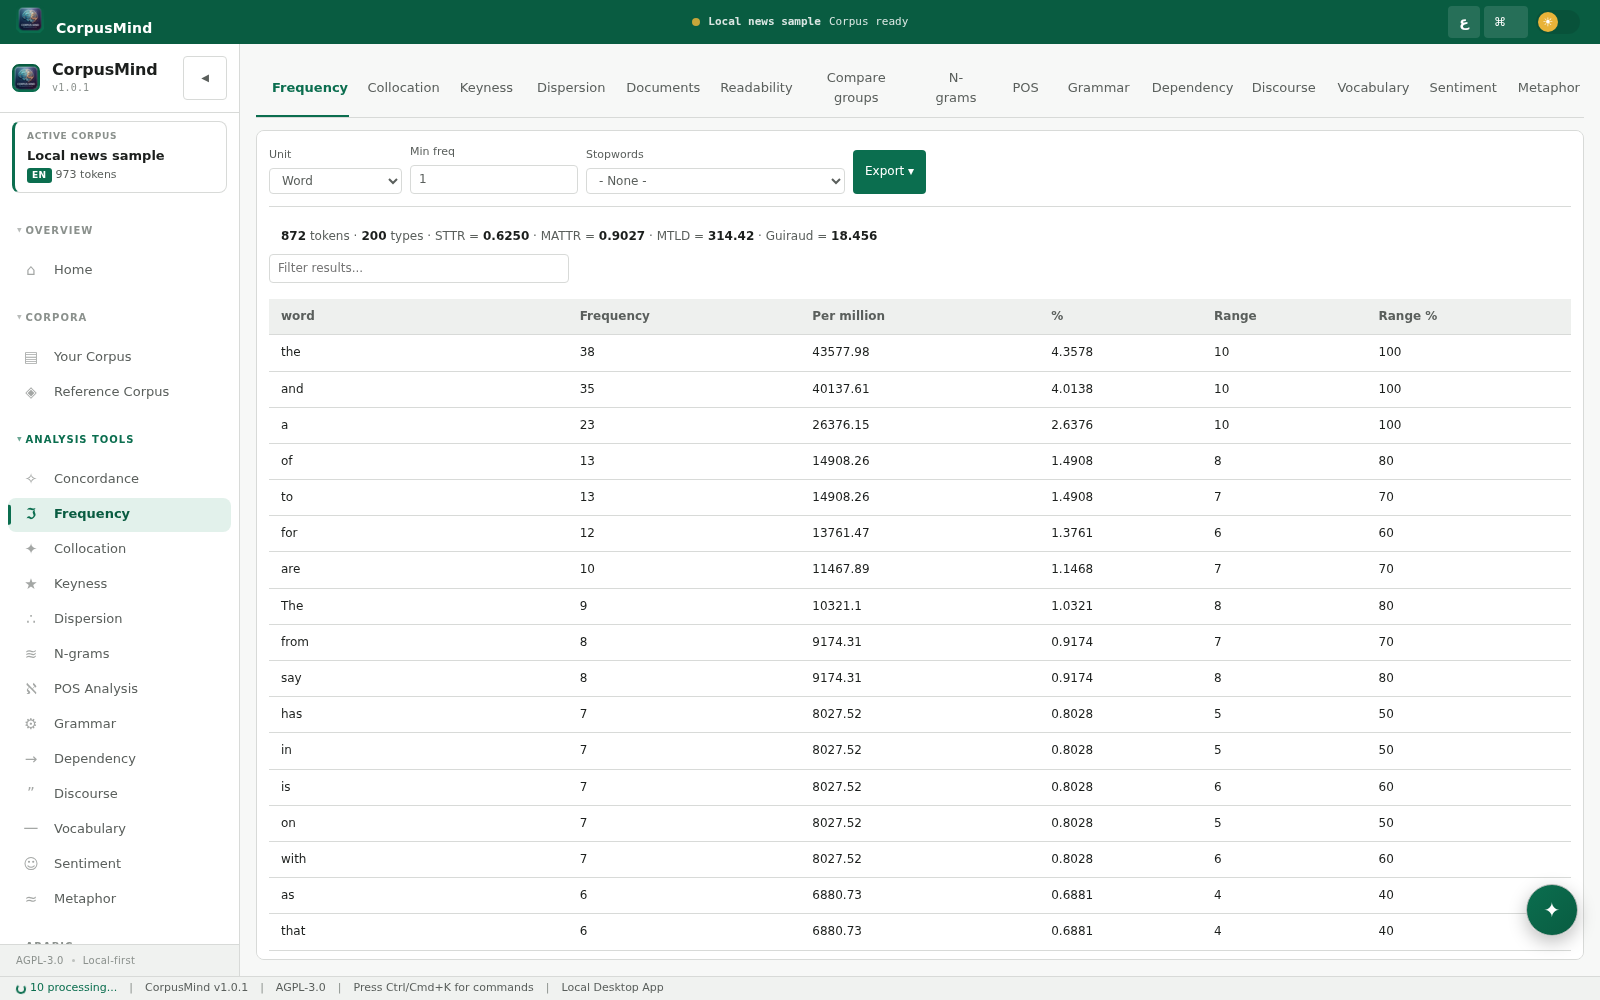
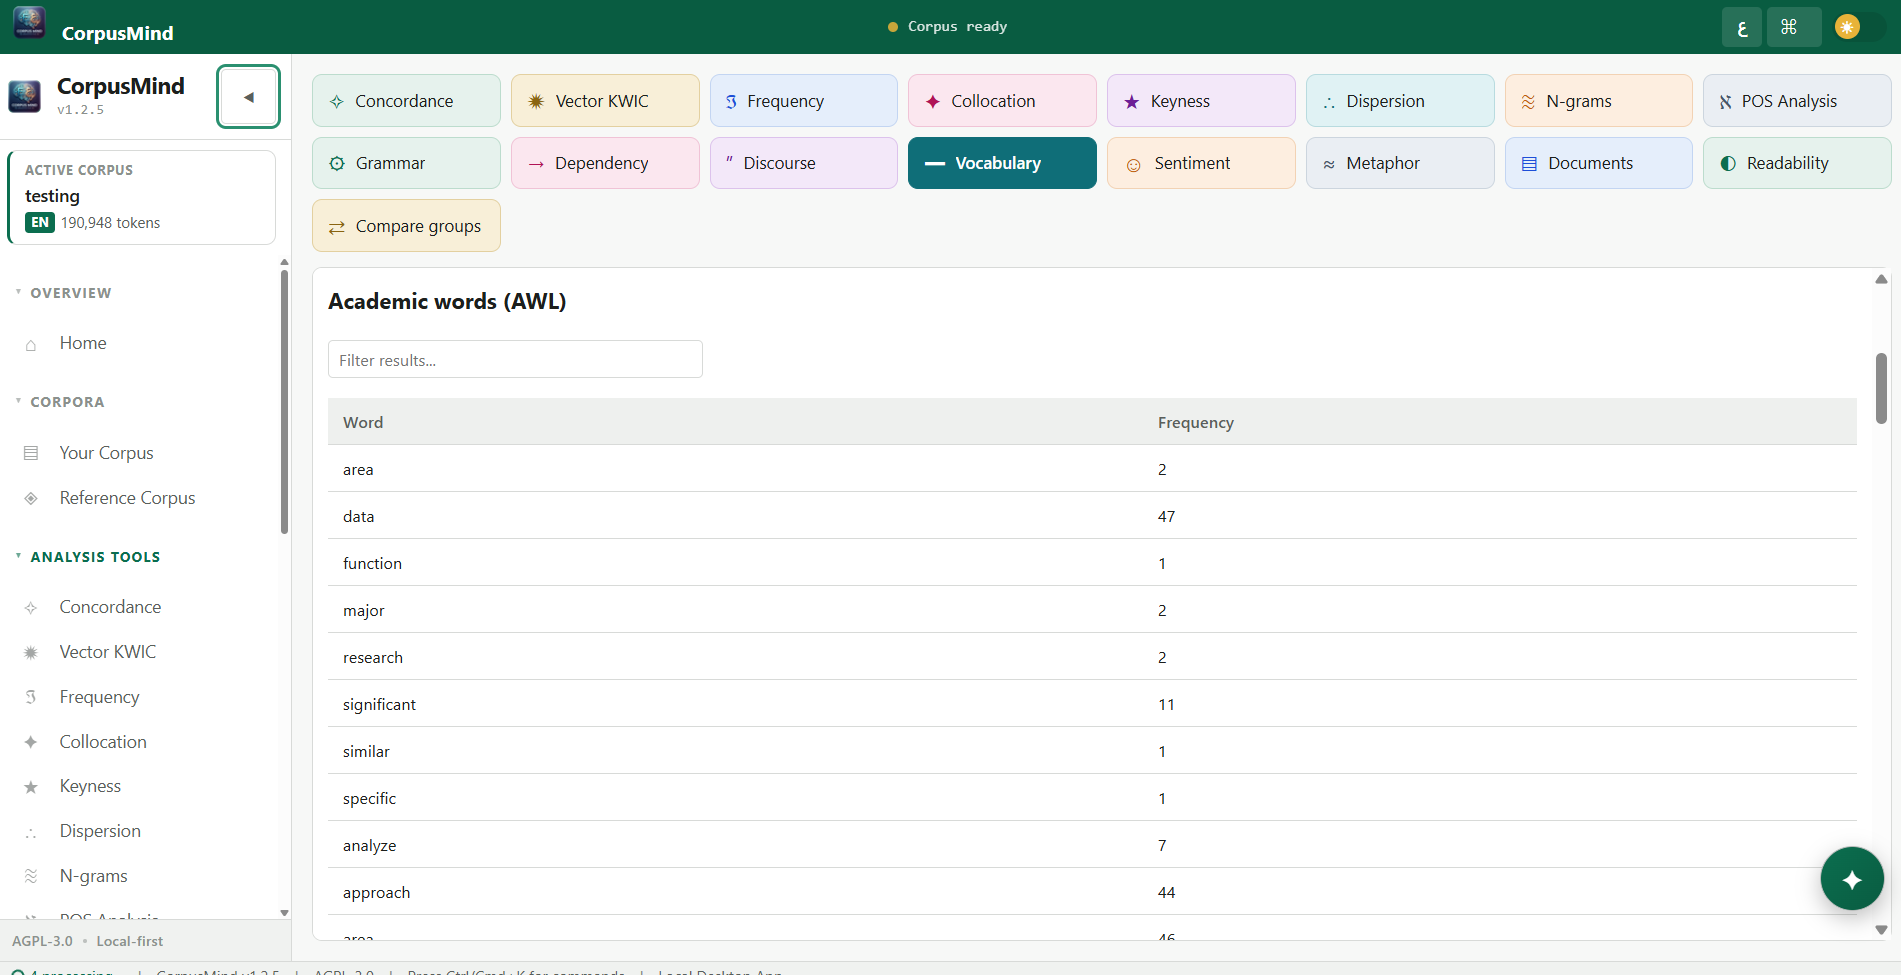
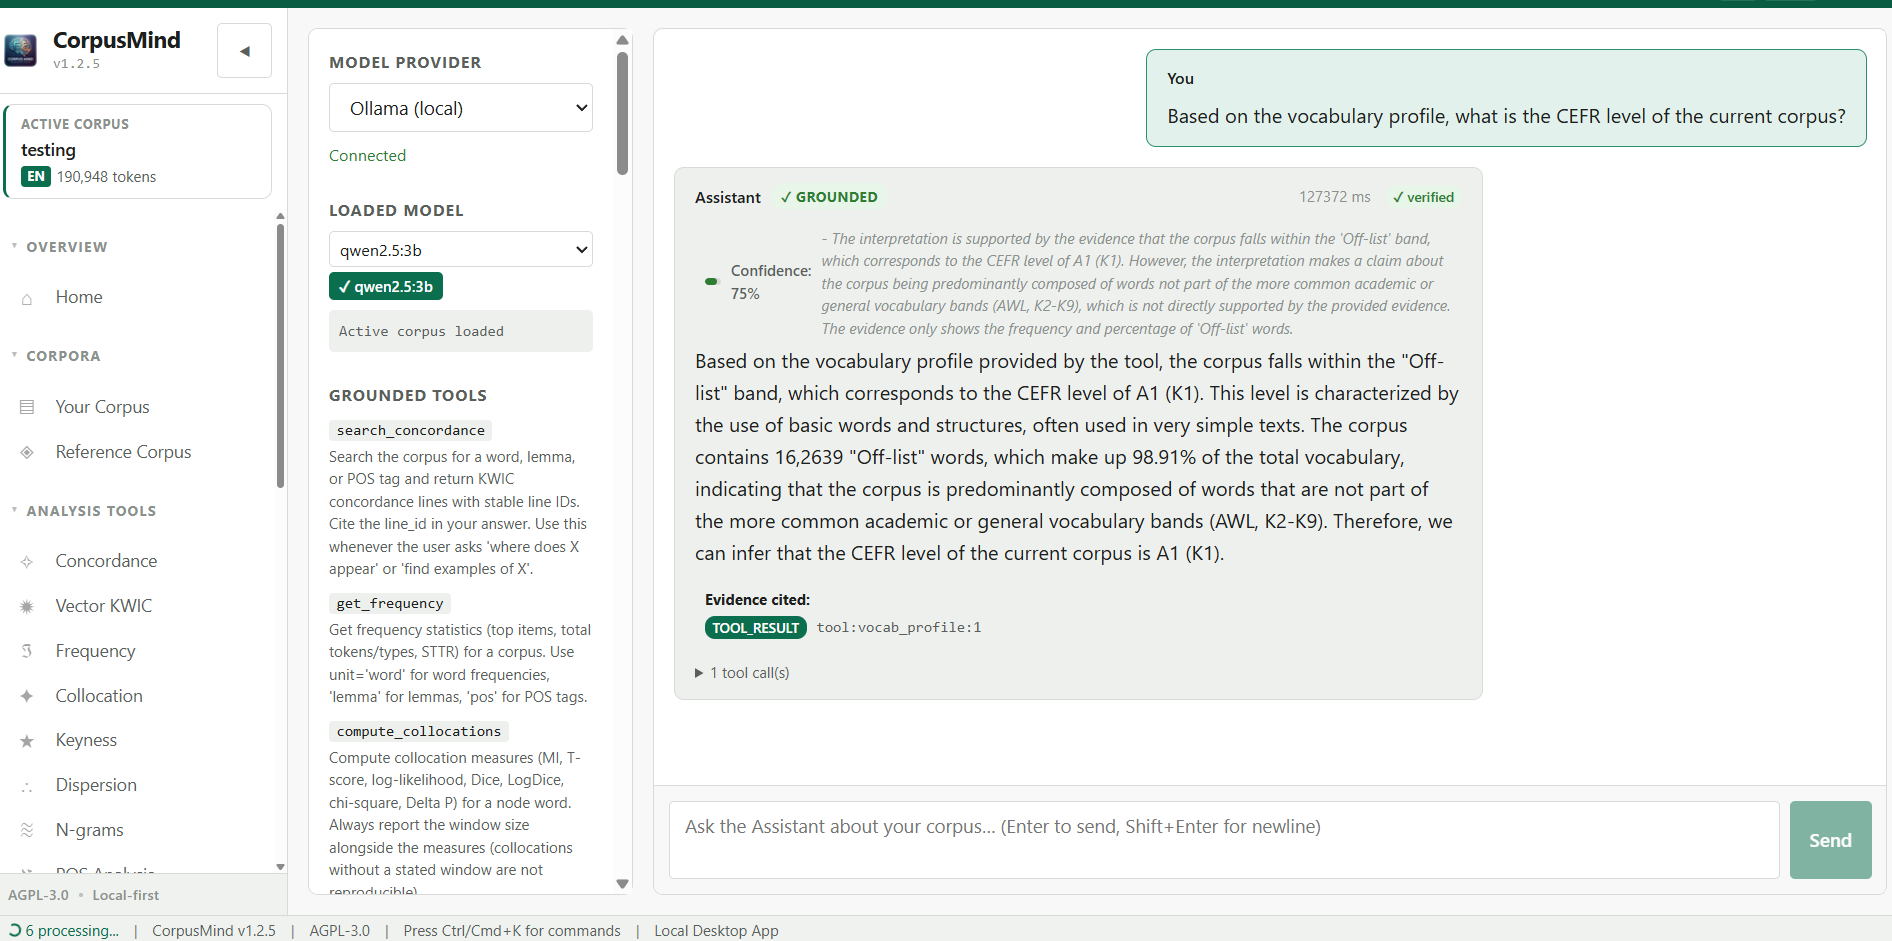
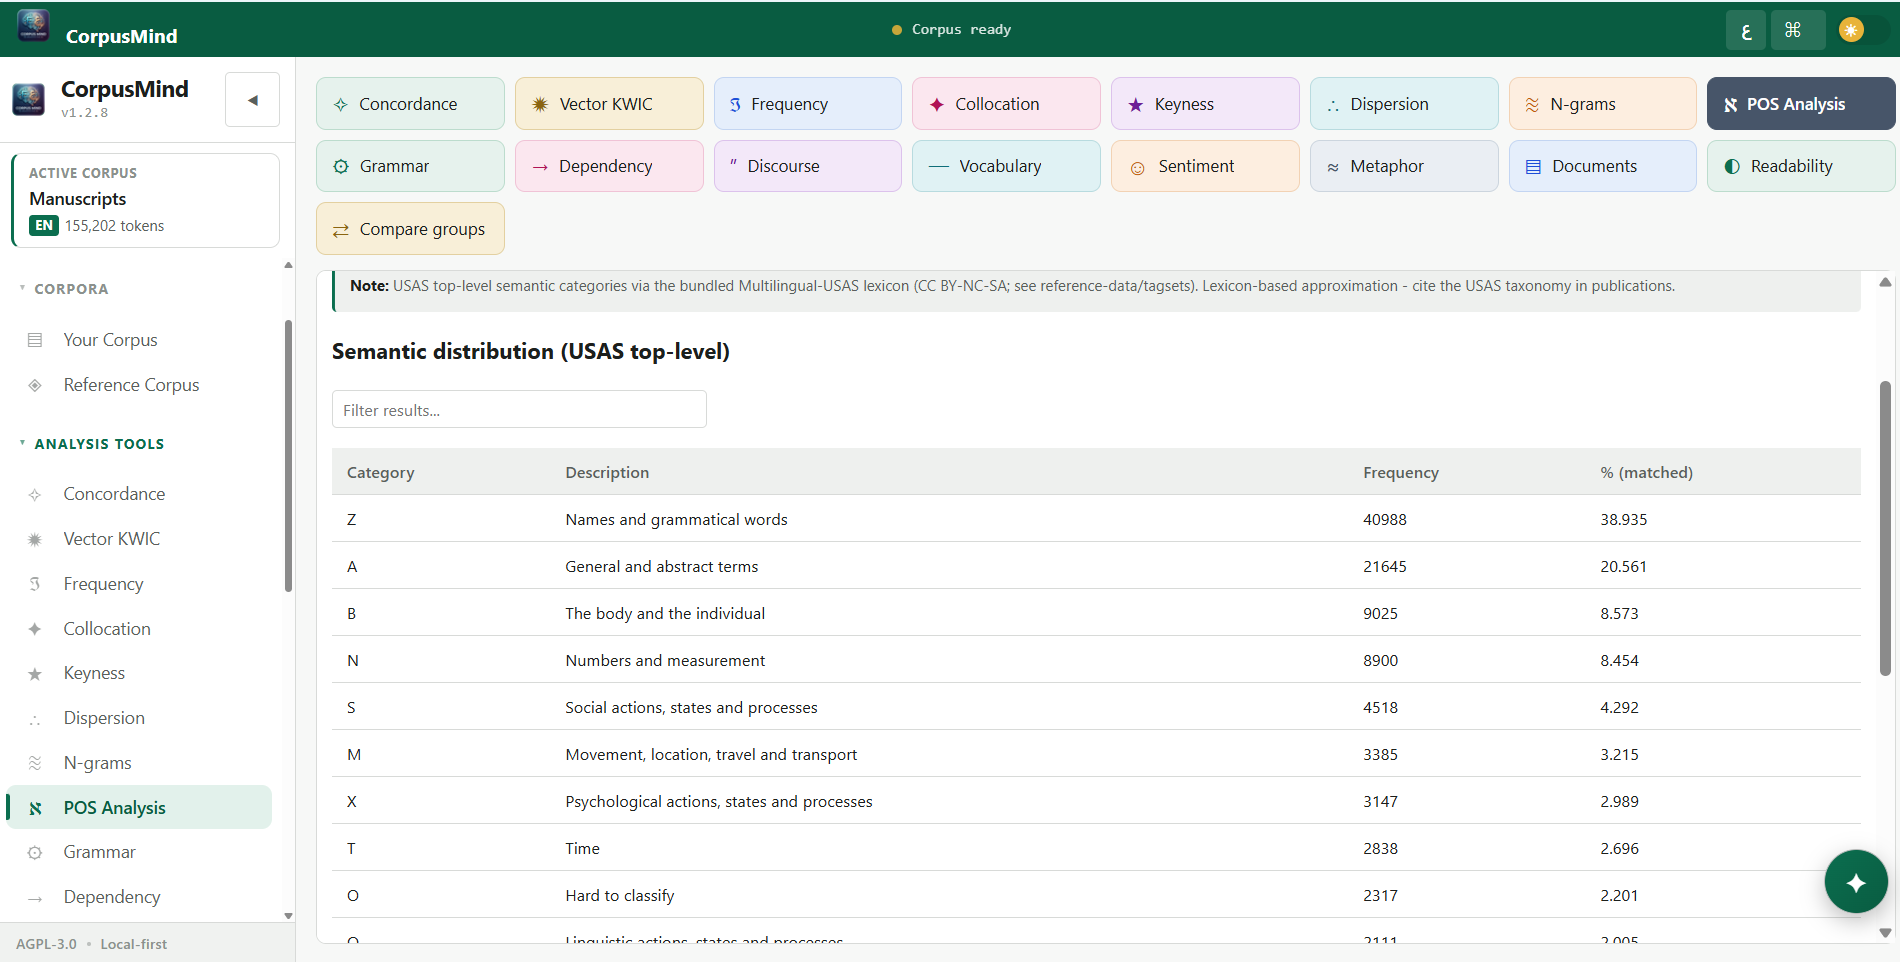
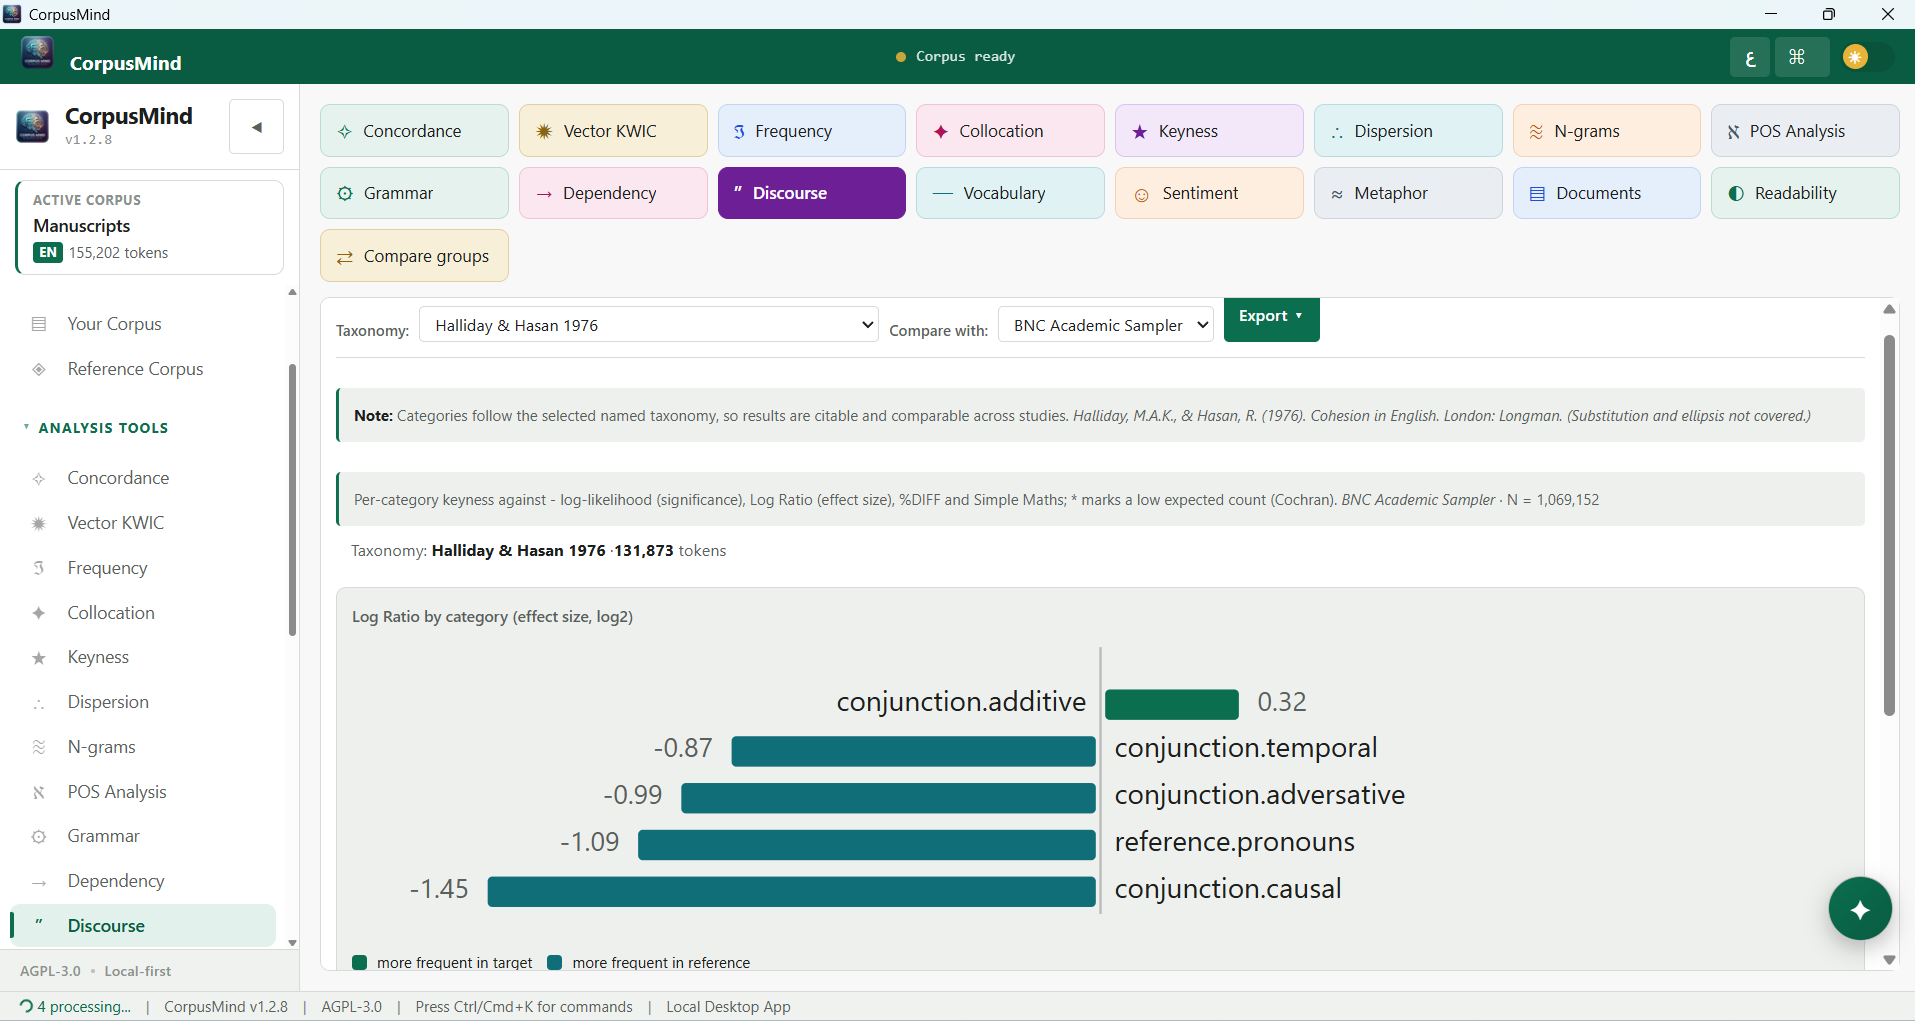
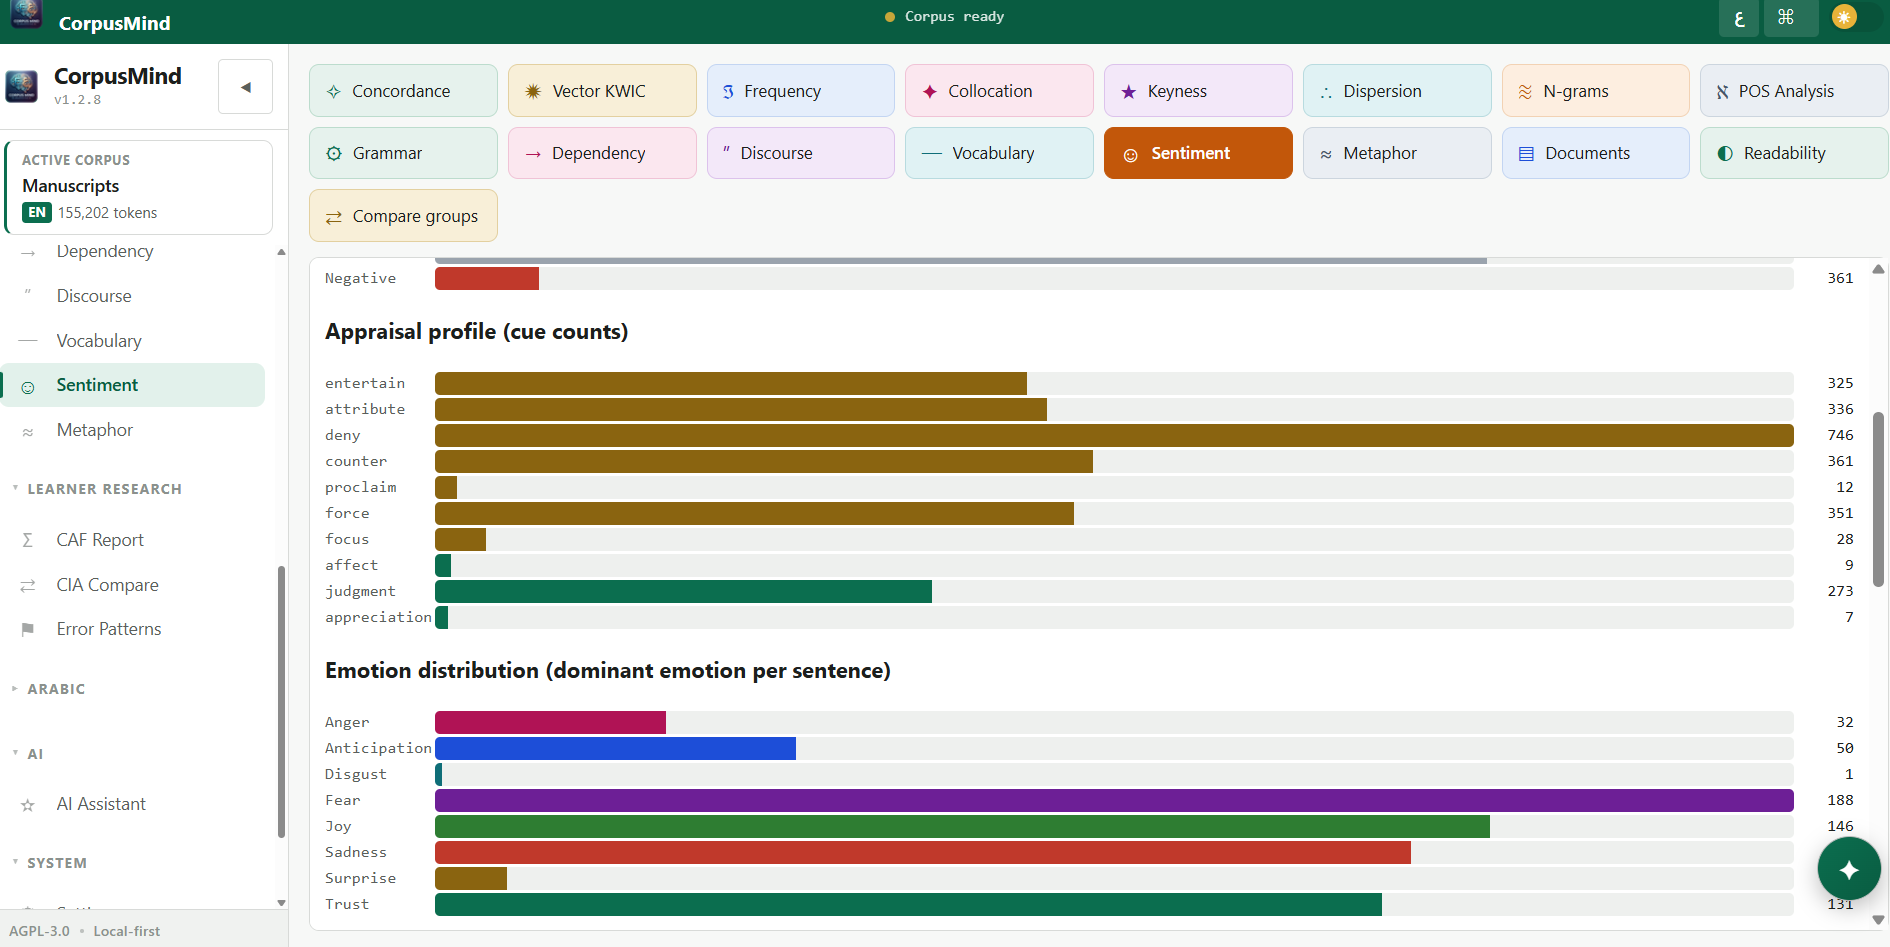
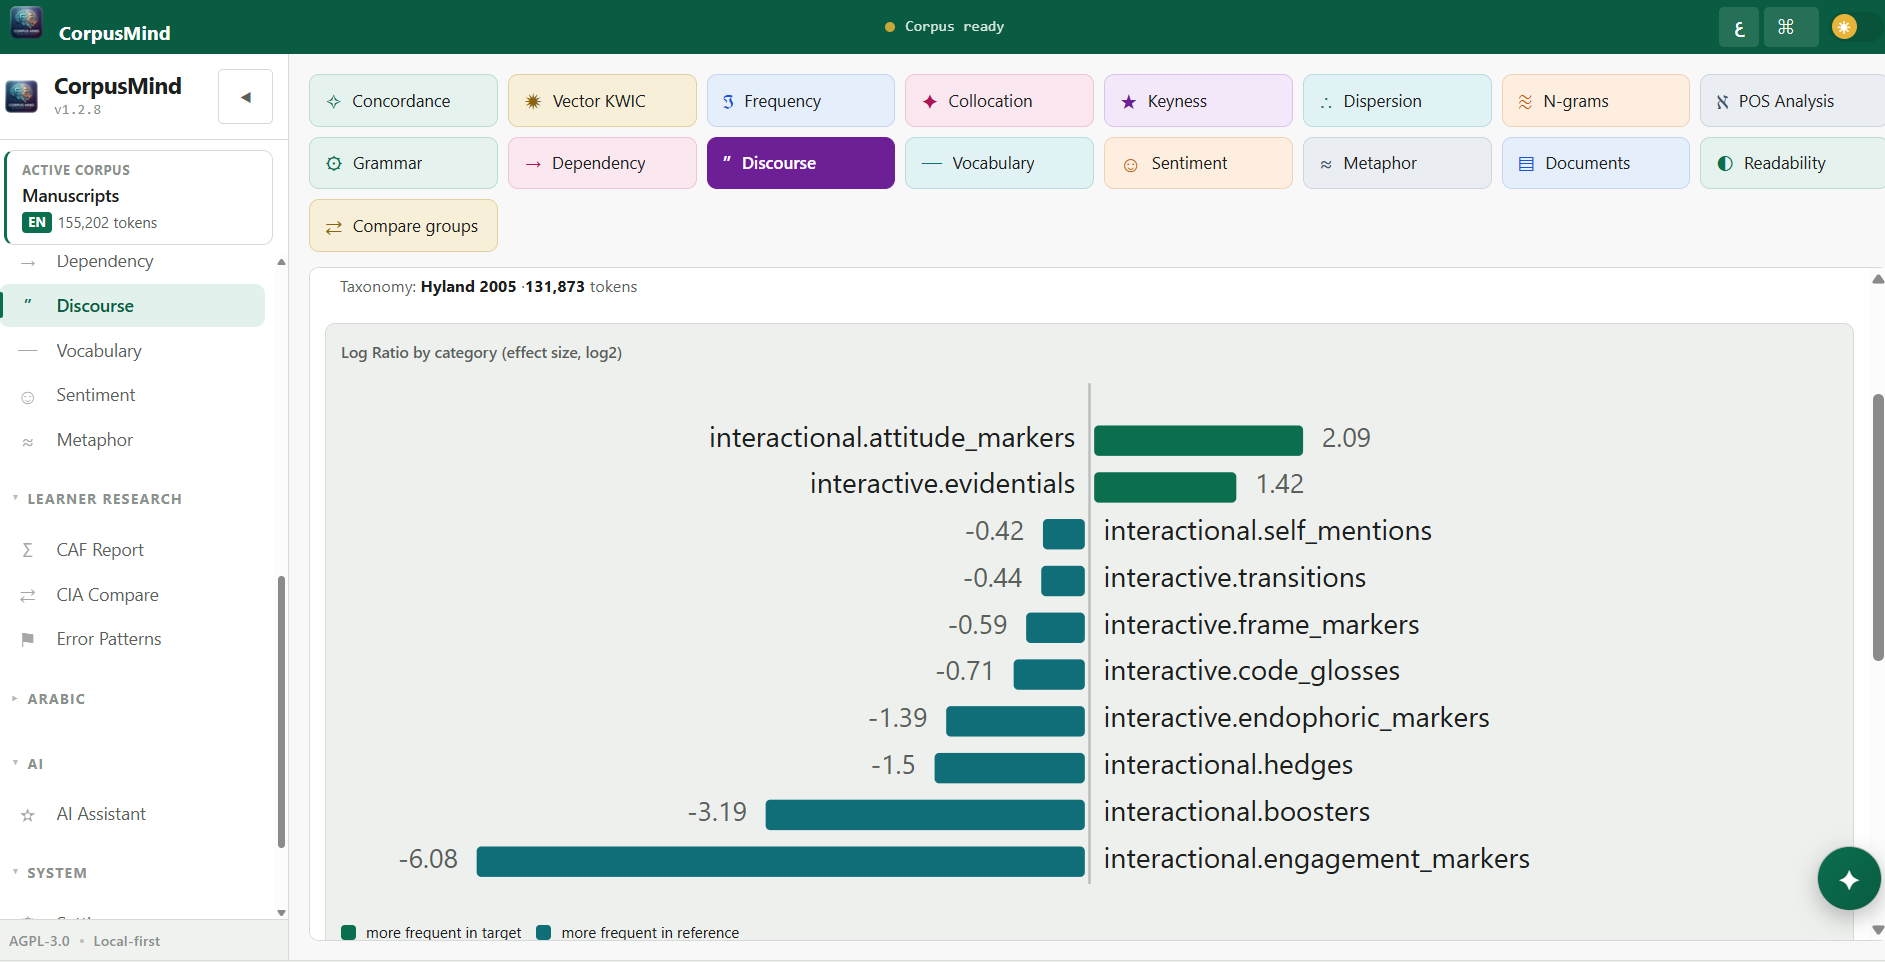
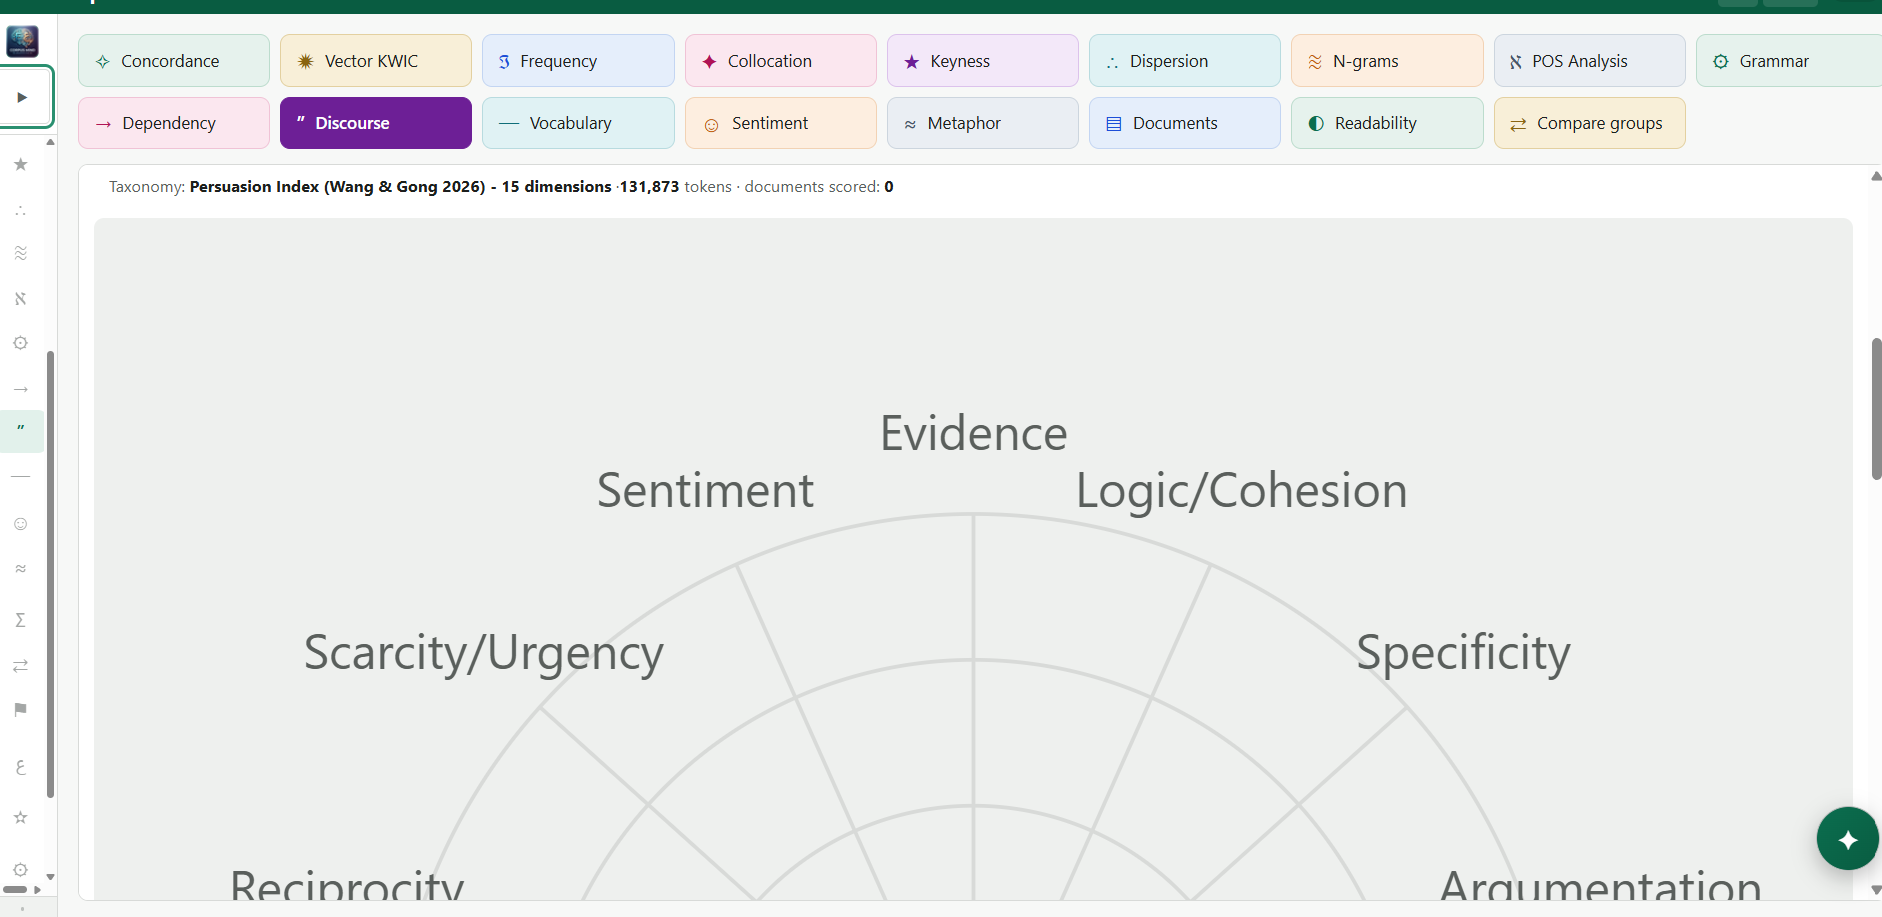
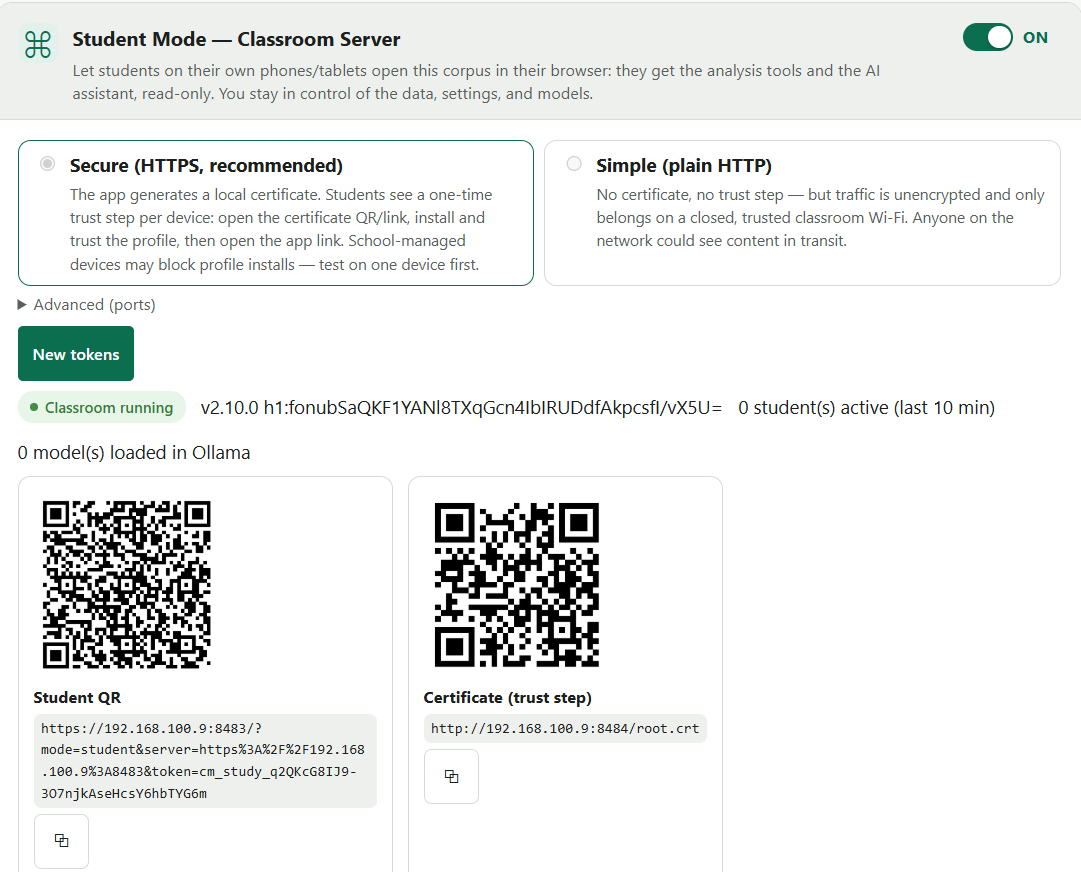
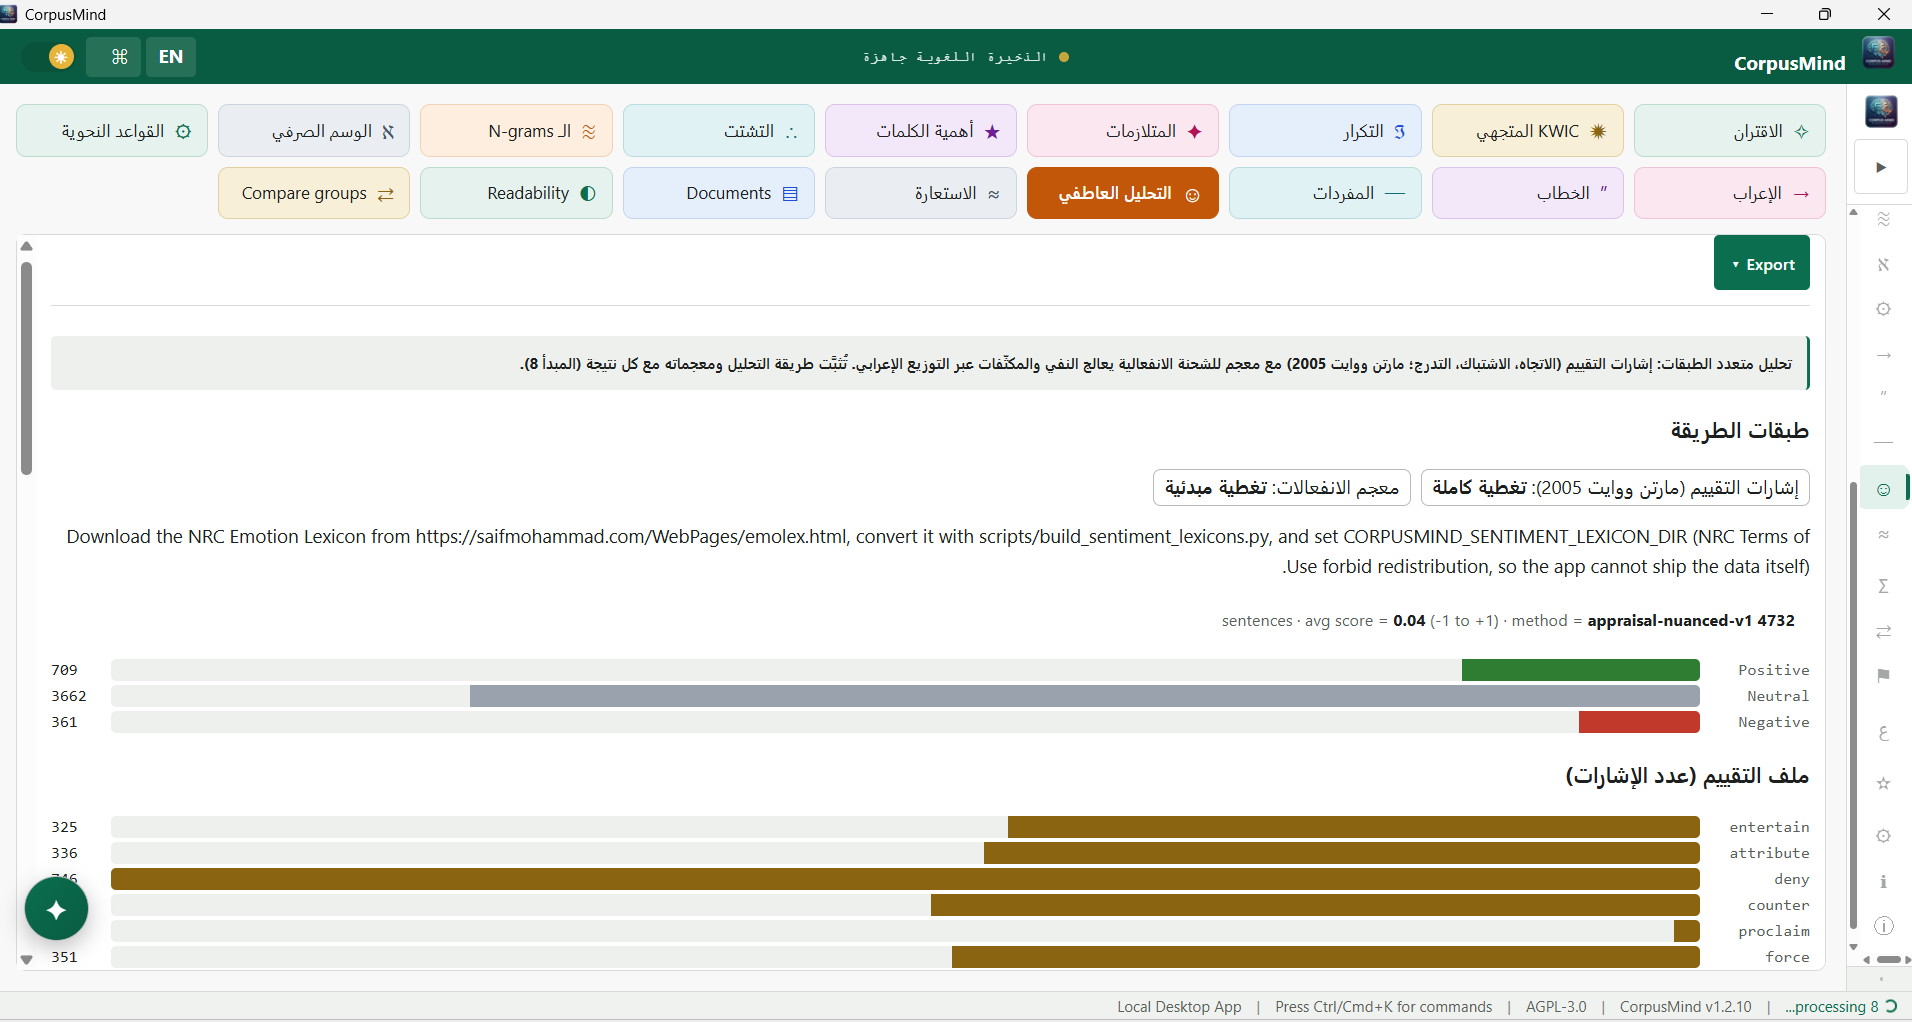
pa*), colour-coded POS tags, and lemma columns
الكشف السياقي — بحث KWIC باستعلامات أحرف البدل (pa*) مع وسوم نحوية ملوّنة وأعمدة التصريف
Click any slide to view it full-size · Try the live PWA انقر على أي شريحة لعرضها بحجم كامل · جرّب PWA مباشرة
Why CorpusMind?
لماذا كوربَس مايند؟
All-in-One Workbench
ورشة عمل متكاملة
Concordance (Simple or CQL query language), frequency, collocation (8 measures), keyness (6 measures), dispersion (4 measures), n-grams, POS, grammar, dependency, vocabulary profiling, sentiment, metaphor, metadiscourse, semantic Vector KWIC, and a Learner Research suite (CAF, CIA, error patterns) — all in one application, all sharing one project system, with one-click Arabic normalization across the search tools, an editable stopword / word-list manager, and built-in Smart Troubleshooting diagnostics when something needs a closer look. No more switching between AntConc for concordance, a separate tagger for POS, a Python script for statistics, and a manual coder for discourse frameworks.
كشف سياقي (بسيط أو بلغة استعلام CQL)، وتردد، وتضايق (8 مقاييس)، وتمييز (6 مقاييس)، وتشتت (4 مقاييس)، وn-grams، وفئة نحوية، وقواعد، وتحليل تبعي، وتصنيف معجمي، ومشاعر، واستعارة، وما وراء الخطاب، والبحث السياقي الدلالي (Vector KWIC)، ومجموعة أبحاث لغة المتعلم (CAF وCIA وأنماط الأخطاء) — كلها في تطبيق واحد، كلها تشترك في نظام مشروع واحد، مع تبديل عربي موحّد بنقرة واحدة عبر أدوات البحث، ومدير قوائم كلمات الإيقاف القابل للتحرير، وتشخيصات Smart Troubleshooting المدمجة حين يحتاج أمرٌ إلى فحص أدق. لا مزيد من التنقل بين AntConc للكشف السياقي، ووسم منفصل للفئة النحوية، وسكربت بايثون للإحصاء، ومُرمِّز يدوي لأطر الخطاب.
First-Class Arabic Support
دعم عربي من الدرجة الأولى
Built-in CAMeL Tools integration delivers Arabic morphology (root, pattern, lemma, stem, Buckwalter transliteration), dialect identification (MSA, Egyptian, Gulf, Levantine), register classification, bilingual parallel concordance and translation, sentiment analysis, and full RTL interface mirroring. No other free corpus tool offers this depth of Arabic NLP out of the box — AntConc and #LancsBox treat Arabic as plain text, and Sketch Engine requires a paid subscription for its Arabic sketch grammar.
تكامل مدمج مع CAMeL Tools يوفّر الصرف العربي (جذر، وزن، تصريف، stem، تحويل باكوالتر)، وتحديد اللهجة (الفصحى، المصرية، الخليجية، الشامية)، وتصنيف السجل، والكشف السياقي المتوازي ثنائي اللغة والترجمة، وتحليل المشاعر، وعكس كامل لواجهة RTL. لا تقدّم أي أداة تحليل لغوي مجانية أخرى هذا العمق من معالجة اللغة العربية جاهزة — AntConc و#LancsBox يعاملان العربية كنص عادي، وSketch Engine يتطلب اشتراكاً مدفوعاً لقواعد الرسم العربية.
Five Languages, Honestly Supported
خمس لغات، بدعم صادق
Urdu (ur), Hindi (hi), and Farsi/Persian (fa) are first-class corpus languages alongside English and Arabic. Each gets its own normalizer — Persian and Urdu unify Arabic-keyboard lookalikes (ي→ی، ك→ک؛ الأردية أيضاً ه→ہ), Hindi folds nukta — and the engine never applies Arabic rules to them. A language capability registry drives the UI with a per-tool support matrix (supported / partial / unavailable, with a reason) instead of silent fallbacks: sentence splitting honours the Hindi danda and the Urdu full stop, ZWNJ is preserved by default, script detection keeps Persian and Urdu out of Arabic resources, and every language ships with a bundled top-1000 keyness baseline and an editable stopword list. Noto Nastaliq Urdu and Noto Sans Devanagari render KWIC and network exports correctly, and CSV exports carry a UTF-8 BOM so your text survives Excel.
الأردية (ur) والهندية (hi) والفارسية (fa) لغات مجموعات لغوية من الدرجة الأولى إلى جانب الإنجليزية والعربية. لكل لغة مُطبِّعها الخاص — توحّد الفارسية والأردية الحروفَ المتشابهة في لوحة المفاتيح العربية (ي→ی، ك→ک؛ والأردية أيضاً ه→ہ)، وتُسوّي الهندية النقطةَ السفلية — ولا يطبّق المحرك قواعد العربية عليها أبداً. ويقود سجلّ قدرات اللغات الواجهة بمصفوفة دعم لكل أداة (مدعومة / جزئية / غير متاحة، مع السبب) بدلاً من السقوط الصامت: تقسيم الجمل يحترم الدندا الهندية ونقطة الأردية، ويُحافَظ على ZWNJ افتراضياً، ويمنع كشف نظام الكتابة إقحام الفارسية والأردية في موارد العربية، ولكل لغة أساس تمييز جاهز لأكثر 1000 كلمة شيوعاً وقائمة إيقاف قابلة للتحرير. ويعرض خطا نوتو نستعليق الأردية ونوتو سانس ديفاناغاري نتائج KWIC وتصديرات الشبكة بشكل صحيح، وتحمل تصديرات CSV ترميز UTF-8 BOM لتنجو نصوصك في Excel.
Learner Corpus Research
أبحاث لغة المتعلم
A dedicated suite for learner-corpus research grounded in the current literature (Housen & Kuiken 2009; Granger 1998): a CAF Report with the full lexical-diversity battery (TTR, MATTR, MTLD, HD-D, Guiraud) and syntactic-complexity indices, groupable by L1 or CEFR level; CIA Compare for Contrastive Interlanguage Analysis against a reference corpus or another L1; rule-based error-pattern candidates (articles, prepositions, agreement, Arabic hamza and ة/ه) flagged for human verification; and an AI-vs-learner comparator that runs the same CAF battery on a pasted AI text. Everything exports with formulas and citations.
مجموعة مخصصة لأبحاث لغة المتعلم مستندة إلى الأدبيات الحالية (Housen وKuiken 2009؛ Granger 1998): تقرير CAF ببطارية التنوع المعجمي الكاملة (TTR وMATTR وMTLD وHD-D وGuiraud) ومؤشرات التعقيد التركيبي، قابلة للتجميع حسب اللغة الأم أو مستوى CEFR؛ ومقارنة CIA للتحليل التقابلي للغة الوسطى مقابل مجموعة مرجعية أو لغة أم أخرى؛ ومؤشرات أنماط أخطاء قائمة على القواعد (أدوات التعريف، وحروف الجر، والمطابقة، والهمزة والة/ه العربية) تُعرض للتحقق البشري؛ ومقارن بين نصوص الذكاء الاصطناعي ونصوص المتعلمين يشغّل بطارية CAF نفسها على نص AI ملصق. وكل ذلك يُصدَّر مع الصيغ والاستشهادات.
Vector KWIC — Semantic Search
الكشف السياقي المتجهي — بحث دلالي
Go beyond exact keyword matching, following Anthony (2025, Applied Corpus Linguistics 5(3): 100164, doi.org/10.1016/j.acorp.2025.100164): Mode A re-ranks classic keyword KWIC lines by the cosine similarity between each context's embedding and your research query, so lines sharing the meaning of your query surface first; Mode B runs a capped semantic sentence search and reports its coverage honestly. Powered by the multilingual bge-m3 embedding model (strong Arabic support) with one-click download through Ollama, local vector caching in SQLite, and raw cosine values — never dressed up as a confidence score.
تجاوز مطابقة الكلمات المفتاحية الحرفية، وفق أنثوني (2025، Applied Corpus Linguistics 5(3): 100164، doi.org/10.1016/j.acorp.2025.100164): يعيد النمط الأول ترتيب سطور الكشف السياقي التقليدي بحسب تشابه جيب التمام بين تضمين كل سياق واستعلامك البحثي، فتتصدر السطور التي تشارك معنى استعلامك؛ ويجري النمط الثاني بحثاً دلالياً محدوداً على مستوى الجمل مع الإبلاغ عن تغطيته بصدق. يعمل بالنموذج متعدد اللغات bge-m3 (دعم قوي للعربية) مع تنزيل بنقرة واحدة عبر Ollama، وتخزين محلي للمتجهات في SQLite، وقيم جيب تمام خام — لا تُقدَّم أبداً كدرجة ثقة.
Grounded AI Assistant
مساعد ذكي اصطناعي مؤسَّس
A tool-calling agent with 27 registered tools that queries the corpus, the statistics, and the vision pipeline. Every answer is either grounded (backed by a cited concordance line, collocation result, or vision annotation) or explicitly flagged as unsupported. Connect it to a local LLM via Ollama for fully offline operation, or to a remote provider (OpenAI, Anthropic) when you choose. No other corpus tool integrates an AI assistant with a citation-enforced contract.
عميل استدعاء أدوات بـ 27 أداة مسجّلة يستعلم المجموعة اللغوية والإحصائيات وخط المعالجة البصري. كل إجابة إما مؤسَّسة (مدعومة بسطر سياقي مُستشهَد به أو نتيجة تضايق أو شرح بصري) أو مُعلَّمة صراحةً كـ غير مدعومة. اربطه بنموذج لغوي محلي عبر Ollama لعمل غير متصل بالكامل، أو بمزوّد بعيد (OpenAI، Anthropic) عندما تختار. لا تدمج أي أداة تحليل لغوي أخرى مساعداً ذكياً اصطناعياً بعقد إلزامي بالاستشهاد.
Reproducible by Design
قابل لإعادة الإنتاج بالتصميم
Every analytical operation emits a YAML provenance record: corpus ID, pipeline recipe, statistical measure with parameters, software version, timestamp, and (if used) which AI provider processed the query. Export a methods.pdf that drafts your manuscript's methodology section for you, with formal definitions and primary-literature citations for every measure. Peer reviewers can verify the entire analytical chain — something no other free corpus tool offers.
كل عملية تحليلية تُصدر سجل إثبات بصيغة YAML: معرّف المجموعة، وصفة الخط، والمقياس الإحصائي مع المعاملات، وإصدار البرنامج، والطابع الزمني، و(إن استُخدم) أي مزوّد ذكاء اصطناعي عالج الاستعلام. صدّر methods.pdf يصيغ قسم المنهجية في مخطوطتك لك، بتعريفات رسمية واستشهادات بالأدبيات الأولية لكل مقياس. يمكن للمحكّمين التحقق من السلسلة التحليلية كاملة — شيء لا تقدّمه أي أداة تحليل لغوي مجانية أخرى.
Free and Open Source, Forever
مجاني ومفتوح المصدر، للأبد
Released under AGPL-3.0-only with no subscription fees, no feature tiers, no telemetry, and no vendor lock-in. Compare with Sketch Engine at €7.09/month (academic) or €428+/year (institutional). The project is not funded by any institution; it was built by the authors out of responsibility to the linguist community. Anyone can read, modify, and redistribute the source code.
صدر تحت AGPL-3.0-only بلا رسوم اشتراك، بلا طبقات ميزات، بلا قياسات استخدام، وبلا قفل للمزوّد. قارن بـ Sketch Engine بـ 7.09 يورو/شهر (أكاديمي) أو 428+ يورو/سنة (مؤسسي). المشروع غير مموّل من أي مؤسسة؛ بناه المؤلفان من مسؤولية تجاه مجتمع اللغويين. يمكن لأي شخص قراءة الكود المصدري وتعديله وإعادة توزيعه.
Classroom Ready (Student Mode)
جاهز للفصل الدراسي (وضع الطالب)
A teacher-as-server classroom mode: the teacher's desktop app opens a scoped classroom server, and students join from their own phones or tablets with a URL or QR code — read-only access to the analysis tools and the grounded AI assistant over the teacher's corpora. Concurrent seats are capped by the teacher's device capabilities and the local LM's compute and memory footprint, and an anonymous audit log records every student query together with the model's answer — with no IPs, tokens, or session IDs ever written to it. Students never see the teacher's files, settings, or chat history.
وضع الفصل الدراسي بوصف المعلم خادماً: يفتح تطبيق المعلم المكتبي خادم فصل دراسي محدود النطاق، وينضم الطلاب من هواتفهم أو أجهزتهم اللوحية عبر رابط أو رمز QR — بوصول للقراءة فقط إلى أدوات التحليل والمساعد الذكي المؤسَّس على مجموعات المعلم اللغوية. تُحدَّد المقاعد المتزامنة بقدرات جهاز المعلم وموارد النموذج المحلي الحسابية والذاكرية، ويسجّل سجل تدقيق مجهول الهوية كل استعلام من طالب مع إجابة النموذج الكاملة — دون كتابة أي عناوين IP أو رموز وصول أو معرّفات جلسات فيه على الإطلاق. ولا يرى الطلاب ملفات المعلم ولا إعداداته ولا سجل محادثاته.
How CorpusMind Compares
كيف يقارن كوربَس مايند
| Featureالميزة | CorpusMind | AntConc | Sketch Engine | #LancsBox | Voyant Tools |
|---|---|---|---|---|---|
| Priceالسعر | Free (AGPL) | Free | €7.09+/mo | Free | Free |
| Collocation measuresمقاييس التضايق | 8 | 1 | Multiple | Several | 1 |
| Arabic morphologyالصرف العربي | Yes (CAMeL) | No | Yes (paid) | No | No |
| Multimodal / Visionمتعدد الوسائط / الرؤية | Via Lens (free) | No | No | No | No |
| Learner research (CAF · CIA)أبحاث لغة المتعلم (CAF · CIA) | Yes | No | No | No | No |
| Semantic vector search (KWIC)بحث دلالي متجهي (KWIC) | Yes | No | No | No | No |
| AI assistant (grounded)مساعد ذكي (مؤسَّس) | Yes | No | No | No | No |
| Provenance recordsسجلات الإثبات | YAML | No | No | No | No |
| POS / Lemma / Dependencyفئة / تصريف / تبعي | Yes (spaCy) | No | Yes | Limited | No |
| Discourse frameworksأطر الخطاب | 15 | 0 | 0 | 0 | 0 |
| Word SketchWord Sketch | Roadmap | No | Yes | No | No |
| Ready-made corporaمجموعات جاهزة | Corpus Hub + BYO | No | Yes | Yes (BNC) | No |
These tools are complementary, not mutually exclusive. Many researchers use Voyant for a quick visual overview, CorpusMind for rigorous analysis, and Sketch Engine for Word Sketches. هذه الأدوات متكاملة، لا متنافية. كثير من الباحثين يستخدمون Voyant لنظرة عامة بصرية، وكوربَس مايند للتحليل الصارم، وSketch Engine لـ Word Sketch.
Getting Started
البدء
Download and Install
نزّل وثبّت
Grab the installer for your platform: .dmg for macOS, .exe or .msi for Windows, .AppImage or .deb for Linux. Or try the live PWA in your browser with no installation.
احصل على المثبّت لمنصتك: .dmg لـ macOS، .exe أو .msi لـ Windows، .AppImage أو .deb لـ Linux. أو جرّب PWA مباشرة في متصفحك دون تثبيت.
(Optional) Install a Local Model
(اختياري) ثبّت نموذجاً محلياً
For the AI assistant with full offline operation, install Ollama and pull a model suited to your RAM (e.g. ollama pull llama3.2:3b for 8 GB). For Vector KWIC, pull the multilingual bge-m3 embedding model — Settings → Models offers one-click downloads with live progress, clear error reporting, and curated model cards (e.g. Gemma 4 QAT) with verified tags and sizes. Works with any OpenAI-compatible local endpoint.
للمساعد الذكي بعمل غير متصل بالكامل، ثبّت Ollama واسحب نموذجاً يناسب رامك (مثل ollama pull llama3.2:3b لـ 8 جيجا). وللكشف السياقي المتجهي، اسحب نموذج التضمين متعدد اللغات bge-m3 — من الإعدادات ← النماذج حيث التنزيل بنقرة واحدة مع تقدم مباشر ورسائل خطأ واضحة وبطاقات نماذج موصى بها (مثل Gemma 4 QAT) بوسوم وأحجام موثّقة. يعمل مع أي نقطة نهاية محلية متوافقة مع OpenAI.
Import a Corpus and Analyse
استورد مجموعة لغوية وحلّل
Create a project, import documents (TXT, DOCX, PDF, HTML, XML, CSV, Markdown) — or skip importing and pull an open corpus straight from the built-in Corpus Hub (Wikipedia live search, HuggingFace datasets, OPUS) — and start analysing. The pipeline recipe is recorded for every document. Export results to Excel, Word, PDF, or LaTeX with provenance metadata for peer review.
أنشئ مشروعاً، واستورد وثائق (TXT، DOCX، PDF، HTML، XML، CSV، Markdown) — أو تجاوز الاستيراد واسحب مجموعة مفتوحة مباشرة من Corpus Hub المدمج (بحث ويكيبيديا الحي، ومجموعات HuggingFace، وشذرات OPUS) — وابدأ التحليل. تُسجَّل وصفة الخط لكل وثيقة. صدّر النتائج إلى Excel أو Word أو PDF أو LaTeX ببيانات إثبات للتحكيم.
Research Transparency Notice
إشعار الشفافية البحثية
CorpusMind v1.2.13 — © 2026 Dr. Waleed Mandour (Sultan Qaboos University) and Prof. Wesam Ibrahim (Princess Nourah Bint Abdulrahman University). Released under the GNU Affero General Public License v3.0 (AGPL-3.0-only). This project is not funded by any institution; it was developed independently by the authors out of responsibility to the linguist community. Engineering support from Super Z (GLM model, Z.ai) under Dr. Mandour's supervision; all code was reviewed and committed by the human authors.
كوربَس مايند v1.2.13 — © 2026 د. وليد مندور (جامعة السلطان قابوس) وأ.د. وسام إبراهيم (جامعة الأميرة نورة بنت عبدالرحمن). صدر تحت رخصة جنو أفيرو العامة الإصدار 3.0 (AGPL-3.0-only). هذا المشروع غير مموّل من أي مؤسسة؛ طوّره المؤلفان بشكل مستقل من مسؤولية تجاه مجتمع اللغويين. دعم هندسي من Super Z (نموذج GLM، Z.ai) تحت إشراف د. مندور؛ راجع المؤلفون البشريون كل الكود وأرسلوه.
Persistent identifier (all versions): https://doi.org/10.5281/zenodo.23265315
Versioned DOIs: Each release gets its own Zenodo DOI. The concept DOI (all versions) is 10.5281/zenodo.23265315. Downloads: Binary installers are on GitHub Releases for fast direct downloads. The Zenodo record provides the permanent DOI for citation and archival.
المُعرّف الدائم: https://doi.org/10.5281/zenodo.23265315
Cite CorpusMind
اقتبس كوربَس مايند
If you use CorpusMind in your research, teaching, or published work, please cite it using the references below.
إذا استخدمت كوربَس مايند في بحثك أو تدريسك أو عملك المنشور، يرجى اقتباسه باستخدام المراجع أدناه.
Companion Applications
التطبيقات المرافقة
CorpusMind Lens
كوربَس مايند لِنز
A separate installable desktop application for vision-LM-powered multimodal discourse analysis, developed and released in its own repository, separate from the main CorpusMind app. It connects to the same CorpusMind engine and provides image-set management, vision-language-model image description, eight discourse-theoretical frameworks with ?mode=llm support, image-text alignment, cross-image batch analysis, and an ethical consent gate for person-descriptive content.
تطبيق مكتبي مستقل لتحليل الخطاب متعدد الأنماط المدعوم بنماذج الرؤية اللغوية، يُطوَّر ويُصدَر في مستودعه الخاص المنفصل عن تطبيق كوربَس مايند الرئيسي. يتصل بنفس محرك كوربَس مايند ويوفر إدارة مجموعات الصور، ووصف الصور بنماذج الرؤية، وثمانية أطر نظرية مع دعم ?mode=llm، ومحاذاة الصورة والنص، والتحليل الدفعي عبر الصور، وبوابة موافقة أخلاقية للمحتوى الوصفي للأشخاص.
CorpusMind Voice
كوربَس مايند فويس
A local-first audio-to-corpus companion for spoken data, now at v1.1.0. It runs a six-stage fully offline pipeline — ingestion, word-level speech recognition (faster-whisper, tiny → large-v3 downloadable in-app), Montreal Forced Aligner alignment, Praat prosody, bilingual disfluency detection — adds an academic Linguistic Analysis suite (frequency & dispersion, KWIC, keywords, collocations, lexical diversity, readability), and saves to SQLite/JSON/CSV/TEI straight from its tabs before handing the corpus into CorpusMind. Also available as an installable mobile PWA, so the researcher can record and analyse on a phone, entirely offline.
رفيق صوتي محلي أولاً للبيانات المنطوقة. يشغّل خط معالجة محليًا كاملًا من ست مراحل — الاستيعاب، والتعرف على الكلام بطوابع زمنية لكلمة بكلمة (faster-whisper large-v3)، والمحاذاة عبر Montreal Forced Aligner، والتنغيم عبر Praat، وكشف عيوب الطلاقة بلغتين، والتصدير إلى SQLite/JSON/CSV/TEI — ثم يسلّم المجموعة المشروحة مباشرة إلى كوربَس مايند. ومتاح أيضاً كتطبيق ويب تقدمي قابل للتثبيت، ففيستطيع الباحث التسجيل والتحليل على الهاتف دون اتصال بالكامل.
Visit CorpusMind Voice زيارة كوربَس مايند فويس Open the Mobile PWA افتح تطبيق الهاتفAvailable Now for Researchers
متاح الآن للباحثين
Download CorpusMind v1.2.13 — free, open-source, with all features unlocked. No subscription, no telemetry, no vendor lock-in.
نزّل كوربَس مايند v1.2.13 — مجاني، مفتوح المصدر، بكل الميزات مفتوحة. بلا اشتراك، بلا قياسات استخدام، بلا قفل للمزوّد.
Version 1.2.13 · AGPL-3.0-only · Not funded by any institution · Release notes
الإصدار 1.2.13 · AGPL-3.0-only · غير مموّل من أي مؤسسة · ملاحظات الإصدار
Live Statistics
الإحصاءات المباشرة
Downloads by Platform التحميلات حسب المنصة
Data fetched from GitHub Releases API · updates in real time البيانات من واجهة GitHub Releases · تُحدّث في الوقت الفعلي